Compare commits
| Author | SHA1 | Date | |
|---|---|---|---|
 ayo |
f71a483a00 | ||
|
ayo
|
b2b3781aca |
No files matched your search
@@ -2,7 +2,7 @@
|
||||
|
||||
d4r runs NVIDIA's official DLSS Super Resolution library (`nvngx_dlss.dll`) in Windows games on AMD Radeon GPUs under Linux and Proton. The game asks for DLSS as usual; the DLSS network runs on the AMD GPU through [ZLUDA](https://github.com/vosen/ZLUDA) (CUDA on ROCm/HIP), with the heaviest DLSS kernels replaced by hand-written RDNA3 and RDNA4 code.
|
||||
|
||||
**Supported DLSS models:** DLSS 3 CNN (E), DLSS 4 transformer (K, default), and DLSS 4.5 transformer (M). DLSS 5 is not supported.
|
||||
**Supported DLSS models:** DLSS 3 CNN (E), DLSS 4 transformer (K, default), and DLSS 4.5 transformer (M). DLSS 5 is PURPOSELY not supported.
|
||||
|
||||
**Proof of concept:** d4r shows that DLSS can run on an AMD GPU, but it is not really that practical for everyday use yet. It has been tested on one GPU in a handful of games and depends on unreleased patches to ZLUDA and vkd3d-proton.
|
||||
|
||||
@@ -31,23 +31,25 @@ On the same GPU DLSS starts at a disadvantage: its networks were designed for NV
|
||||
|
||||
## Known issues
|
||||
|
||||
- In some games native upscaling can show visible artifacting.
|
||||
- In some games using some models native upscaling can show visible artifacting.
|
||||
|
||||
For users who prioritize fidelity over speed, set `[Kernels] PreferAccuracy = true` in `d4r/d4r.ini` and restart the game. It defaults to `false`. This selects accuracy variants of every native kernel and restores conservative translation settings. It aims to match NVIDIA's arithmetic; 1:1 image quality against RTX DLSS is not yet proven. See [native kernel numerics](docs/native-kernels.md#numerics).
|
||||
|
||||
## GPU support
|
||||
|
||||
d4r builds for RDNA3 and RDNA4. A newly built release compiles native DLSS 4 and 4.5 network kernels for the targets below and selects the matching set at runtime. Only the RX 7700 XT has been tested on a real GPU; RDNA4 runtime and performance remain unverified on hardware.
|
||||
d4r builds for RDNA3 and RDNA4. A newly built release compiles native DLSS 4 and 4.5 network kernels for the targets below and selects the matching set at runtime. Only the RX 7700 XT has been tested by this project on a real GPU; an external video reports DLSS 4.5 running through d4r 0.1.2 on an RX 7900 XTX. RDNA4 runtime and performance remain unverified on hardware.
|
||||
|
||||
| GPU | Chip | FP8 math | Runtime testing |
|
||||
|---|---|---|---|
|
||||
| RX 7700 XT, RX 7800 XT, RX 7700, Radeon PRO W7700 | gfx1101 | widened to f16 | RX 7700 XT only |
|
||||
| RX 7900 GRE / XT / XTX, Radeon PRO W7800 / W7900 | gfx1100 | widened to f16 | untested |
|
||||
| RX 7900 GRE / XT / XTX, Radeon PRO W7800 / W7900 | gfx1100 | widened to f16 | RX 7900 XTX: [external video](https://www.youtube.com/watch?v=_GLjJ2Dn5pU) (DLSS 4.5); other cards untested |
|
||||
| RX 7600 / 7600 XT, RX 7650 GRE | gfx1102 | widened to f16 | untested |
|
||||
| RDNA3 integrated GPUs | gfx1103 | widened to f16 | untested |
|
||||
| RX 9070 XT / 9070 / 9070 GRE, Radeon AI PRO R9700 | gfx1201 | native FP8 (`NativeFp8`, default on) | emulator only |
|
||||
| RX 9060 XT / 9060 | gfx1200 | native FP8 (`NativeFp8`, default on) | compile only |
|
||||
| RDNA2 and older | | | unsupported |
|
||||
|
||||
Native network kernels are built for all listed gfx11/gfx12 targets. Texture kernels are compiled for each target by `d4r_emit` when supplied to the package script; RDNA4 also has a `-fp8` variant. The bridge selects the KFD GPU with the most SIMDs, avoiding an integrated GPU when a discrete GPU is present; `D4R_GPU_ARCH` overrides that choice. Missing native kernels fall back to ZLUDA. Without the native network kernels, NVIDIA's translated DLSS 4 layers produce invalid values and DLSS discards the network's output, so K loses the transformer's image quality. Preset E does not use the native network kernels.
|
||||
Native network kernels are built for all listed gfx11/gfx12 targets. Texture kernels are compiled for each target by `d4r_emit` when supplied to the package script; RDNA4 also has a `-fp8` variant. The bridge selects the KFD GPU with the most SIMDs, avoiding an integrated GPU when a discrete GPU is present; `D4R_GPU_ARCH` overrides that choice. Missing native kernels fall back to ZLUDA and can be much slower. Earlier translated K layers produced invalid values; preserving FP16 denormal handling fixes that failure in recorded captures, but RTX image-quality parity remains unverified. Preset E does not use the native network kernels.
|
||||
|
||||
## How it works
|
||||
|
||||
@@ -136,9 +138,15 @@ Gameplay recordings of each DLSS model at the Quality, Performance and Ultra Per
|
||||
| `packaging/` | the release's `d4r.ini`, OptiScaler settings, user guide and install check |
|
||||
| `docs/` | architecture, build, native kernel and performance notes |
|
||||
|
||||
## Stars
|
||||
## Star History
|
||||
|
||||
[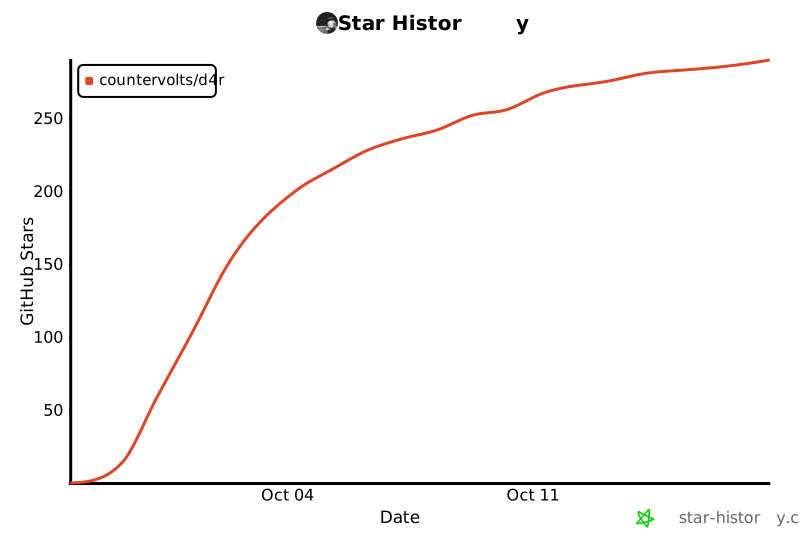](https://star-history.com/#countervolts/d4r&Date)
|
||||
<a href="https://www.star-history.com/?type=date&repos=countervolts%2Fd4r">
|
||||
<picture>
|
||||
<source media="(prefers-color-scheme: dark)" srcset="https://api.star-history.com/chart?repos=countervolts/d4r&type=date&theme=dark&legend=top-left" />
|
||||
<source media="(prefers-color-scheme: light)" srcset="https://api.star-history.com/chart?repos=countervolts/d4r&type=date&legend=top-left" />
|
||||
<img alt="Star History Chart" src="https://api.star-history.com/chart?repos=countervolts/d4r&type=date&legend=top-left" />
|
||||
</picture>
|
||||
</a>
|
||||
|
||||
## License
|
||||
|
||||
|
||||
@@ -19,6 +19,10 @@ The following DirectX 12 games run DLSS Super Resolution through d4r on the test
|
||||
| Ratchet & Clank: Rift Apart | Works; occasional artifacts in the pause menu | Works; minor artifacts with HDR enabled and occasionally in the pause menu | Works; occasional artifacts in the pause menu |
|
||||
| Dying Light: The Beast | Works | Works | Works; small visual artifacts throughout |
|
||||
|
||||
Unsupported games:
|
||||
|
||||
- **DOOM: The Dark Ages:** the game uses Vulkan and has no D3D12 mode. d4r currently supports D3D12 DLSS only, so its DLSS calls cannot reach d4r. The game's hardware ray-tracing requirement is separate from this limitation.
|
||||
|
||||
General notes:
|
||||
|
||||
- Select DLSS in the game's graphics settings where it is offered. OptiScaler can also feed DLSS from a game's FSR or XeSS inputs, but those are a fallback for games that hide DLSS and can ghost or show a black screen.
|
||||
|
||||
@@ -36,9 +36,15 @@ Model = K
|
||||
FrameAge = 0
|
||||
|
||||
[Kernels]
|
||||
; Prefer NVIDIA's original arithmetic over speed for every native kernel and the translated fallback.
|
||||
; Restores intermediate FP8 quantization, per-MMA f16 rounding and original denormal handling; keeps
|
||||
; NGX's synchronizations. Selects accuracy variants in NativeKernelDir*/accuracy (or a marked accuracy
|
||||
; directory directly). Missing accuracy kernels use translated PTX, never the fast set. Slower; this
|
||||
; aims for fidelity, but RTX image parity is not proven. (D4R_PREFER_ACCURACY)
|
||||
PreferAccuracy = false
|
||||
; Native RDNA3 / RDNA4 kernels for the DLSS 4 and 4.5 network layers (replace ZLUDA's translated code).
|
||||
; fast = native kernels with relaxed numerics (visually identical to exact, ~15% faster)
|
||||
; exact = native kernels that reproduce NVIDIA's FP8/f16 rounding bit for bit
|
||||
; fast = native kernels with relaxed numerics (unless PreferAccuracy is true)
|
||||
; exact = a separately built directory with conservative FP8/f16 rounding; not an RTX parity guarantee
|
||||
; off = ZLUDA-translated kernels only
|
||||
; fast/exact need the code objects built by the native-kernel tools ([Paths] NativeKernelDir*).
|
||||
NativeKernels = off
|
||||
@@ -127,3 +133,4 @@ LogDir = auto
|
||||
[Env]
|
||||
; Anything else, passed through as environment variables (one per line):
|
||||
; D4R_SHIM_SPLIT_TIMEOUT_MS = 200
|
||||
; D4R_SHIM_BLOCKING_SYNC = 1 ; yield CPU while waiting for DLSS output
|
||||
+11
-1
@@ -39,7 +39,7 @@ Without the vkd3d-proton patch the shim shows the newest finished result instead
|
||||
|
||||
- **CUDA NGX instead of D3D12 NGX.** NVIDIA's D3D12 path needs NVIDIA's driver. The CUDA path only needs a CUDA driver API, which ZLUDA provides.
|
||||
- **The Ada identity.** NGX picks network weights by GPU architecture. The weights have to match the PTX that ZLUDA compiles, which is sm_89 for DLSS 310.
|
||||
- **Native kernels.** ZLUDA translates NVIDIA's warp-level matrix code faithfully but slowly (register pressure, lane shuffles, per-instruction mode switches). In the DLSS 4 transformer, ZLUDA's translation also produced non-finite outputs, which the final kernel masks, so the network had no effect. The native layers fix both.
|
||||
- **Native kernels.** Translating NVIDIA's warp-level matrix code is slow (register pressure, lane shuffles, per-instruction mode switches). Earlier translated K layers also produced non-finite outputs that the final kernel masked. Native layers avoid that path; the compiler now preserves FP16 denormal requirements too, which fixes the translated failure in recorded captures. Numerical and image-quality parity with RTX hardware remains unverified.
|
||||
- **The GPU-side hand-offs.** With DLSS itself fast, most of the remaining gap to FSR 4 was the GPU idling while CPU threads waited on each other. Moving the waits onto the GPU raised GPU utilisation from about 95% to 99%.
|
||||
|
||||
## Configuration
|
||||
@@ -51,6 +51,7 @@ Without the vkd3d-proton patch the shim shows the newest finished result instead
|
||||
| `[DLSS] Model` | `D4R_DLSS_PRESET` | DLSS network: `E` (CNN), `K` (DLSS 4), `M` (DLSS 4.5) |
|
||||
| `[Latency] FrameAge` | `D4R_SHIM_SPLIT_FRAME`, `D4R_SHIM_MAX_IN_FLIGHT` | 0 = same-frame results; higher values pipeline frames |
|
||||
| `[Kernels] NativeKernels` | `D4R_ZLUDA_NATIVE_DIR` | native kernel directory (`fast` / `exact` / `off`) |
|
||||
| `[Kernels] PreferAccuracy` | `D4R_PREFER_ACCURACY` | default off; accuracy variants for every native family and conservative translation/synchronization settings |
|
||||
| `[Interop] VramInterop` | `D4R_SHIM_VRAM_INTEROP` | keep inputs and output in VRAM |
|
||||
| `[Interop] GpuWait` | `D4R_SHIM_GPU_WAIT` | GPU-side wait for the game's inputs |
|
||||
| `[Interop] LinearInputs` | `D4R_SHIM_LINEAR_INPUTS` | NGX samples the input buffers in place |
|
||||
@@ -88,3 +89,12 @@ The release zip (`scripts/package_release.sh`) is unpacked into the folder that
|
||||
## Logs
|
||||
|
||||
The launcher writes each run's logs to `~/.cache/d4r-dlss-captures/game-<exe>-<time>/`. `d4r_nvngx.log` holds the shim's log. With `[Debug] Profile = true` it also records one `D4R_PROFILE` line per frame, with the stage timings.
|
||||
|
||||
For a CPU-use A/B check, set `D4R_SHIM_BLOCKING_SYNC = 1` under `[Env]` in the game's `d4r.ini`.
|
||||
The VRAM path then requests a blocking event wait for its null-stream output. If ZLUDA and HIP
|
||||
honour the event flag, the waiting thread yields the CPU; an unavailable or failed event falls back
|
||||
to the original context sync. This is opt-in because it changes the wait scope and may add wakeup
|
||||
latency. The profile reports `output_sync_wall`, `output_sync_cpu`, and `output_sync_blocking`;
|
||||
compare CPU use and frame rate in the same scene.
|
||||
The `d2h` field on this path includes the output synchronization wait, even when direct output
|
||||
skips the array-to-buffer copy.
|
||||
+35
-2
@@ -27,6 +27,13 @@ cp target/release/libnvcuda.so ~/.cache/d4r-zluda-current/
|
||||
ln -sf libnvcuda.so ~/.cache/d4r-zluda-current/libcuda.so
|
||||
```
|
||||
|
||||
Build the release ZLUDA library on a system or in a container with GLIBC 2.41 or older. A binary
|
||||
linked on a newer system can require newer GLIBC symbols even when the ZLUDA source does not need new
|
||||
GLIBC features. Before packaging, check it with
|
||||
`scripts/check_glibc_compat.sh 2.41 /path/to/libnvcuda.so`. The release packager runs the same
|
||||
check on ZLUDA, the Wine CUDA bridge, and every bundled ROCm library. Test the rebuilt library
|
||||
with the D3D12 harness and in a game before publishing a release.
|
||||
|
||||
The launcher looks for ZLUDA in `D4R_ZLUDA_DIR` (default `~/.cache/d4r-zluda-current`, or `ZludaDir` in d4r.ini).
|
||||
|
||||
What the patches add:
|
||||
@@ -76,6 +83,8 @@ kernels/build.sh all kernels/out/native
|
||||
|
||||
`kernels/out/native` then holds one code object per replaced DLSS kernel; set `NativeKernelDirFast` in d4r.ini (or `D4R_ZLUDA_NATIVE_DIR`) to it. `kernels/build.sh k` or `m` builds only the network layers and needs neither the DLL nor ZLUDA. The texture kernels (`tex`) extract PTX from your DLL into `kernels/extracted/` and compile it offline for `D4R_GPU_ARCH` through `D4R_ZLUDA_EMIT`; that directory and the build output are git-ignored and must not be redistributed. On gfx12, build a second variant with `D4R_NATIVE_FP8=1` and place it in an `<arch>-fp8` folder.
|
||||
|
||||
To add the accuracy option to a developer set, repeat the build with `D4R_PREFER_ACCURACY=1` and output `kernels/out/native/accuracy` (multi-target builds: `kernels/accuracy/<arch>` and `<arch>-fp8`). Use a separate empty directory; successfully built accuracy sets receive `d4r-accuracy.txt`. Enable `[Kernels] PreferAccuracy = true` and restart. The option defaults to false and never substitutes the fast set when accuracy binaries are absent.
|
||||
|
||||
## 6. Configure and play
|
||||
|
||||
The first launch copies `config/d4r.ini.default` to `~/.config/d4r/d4r.ini`. Set the `[Launch]` paths (Proton, the game's compatdata prefix and the game executable), the `[Paths]` above, and the model in `[DLSS]`, then run:
|
||||
@@ -94,18 +103,42 @@ D4R_OPTISCALER=/path/to/OptiScaler_0.9.4.7z \
|
||||
D4R_DLSS_DLLS=/path/to/310.7/nvngx_dlss.dll:/path/to/310.9/nvngx_dlss.dll \
|
||||
D4R_BUNDLE_DLSS=/path/to/nvngx_dlss.dll D4R_BUNDLE_NGX=/path/to/_nvngx.dll D4R_BUNDLE_TEX=kernels/out/native \
|
||||
D4R_ZLUDA_DIR=~/.cache/d4r-zluda-current D4R_VKD3D_DIR=~/.cache/d4r-vkd3d-d4r D4R_ROCM_DIR=/opt/rocm \
|
||||
D4R_ZLUDA_EMIT=/path/to/zluda/target/release/examples/d4r_emit \
|
||||
scripts/package_release.sh # -> dist/d4r-<version>.zip
|
||||
```
|
||||
|
||||
The script:
|
||||
- builds the shim, the bridge and the network-layer kernels for gfx1100–gfx1103 and gfx1200–gfx1201 by default (`D4R_GPU_ARCHS` can select fewer targets); each gfx12 target also gets an `<arch>-fp8` variant;
|
||||
- builds the shim, the bridge and both fast and accuracy network-layer kernels for gfx1100–gfx1103 and gfx1200–gfx1201 by default (`D4R_GPU_ARCHS` can select fewer targets); each gfx12 target also gets an `<arch>-fp8` variant;
|
||||
- writes the kernel manifest from the DLLs you list (it records hashes of their PTX, nothing else);
|
||||
- stages OptiScaler as `dxgi.dll` with the settings in `packaging/optiscaler.settings`;
|
||||
- adds NVIDIA's two DLLs and any supplied texture kernels (built from NVIDIA's PTX by `kernels/build.sh tex`);
|
||||
- adds NVIDIA's two DLLs and any supplied texture kernels (built from NVIDIA's PTX by `kernels/build.sh tex`); builds accuracy texture sets with `D4R_ZLUDA_EMIT` unless marked prebuilt sets are supplied in `D4R_BUNDLE_TEX/accuracy/<target>`;
|
||||
- zips the result together with the ZLUDA and vkd3d-proton builds, the ROCm runtime (as `d4r/rocm`), `packaging/d4r.ini`, the licenses and the patches.
|
||||
|
||||
The NVIDIA files are not covered by d4r's license; redistributing them is up to whoever publishes the zip. `D4R_BUNDLE_NVIDIA=0` builds `d4r-<version>-nonvidia.zip` without them and without the texture kernels. [architecture.md](architecture.md#portable-installs-the-release-zip) describes how the installed files work together.
|
||||
|
||||
### GLIBC 2.41 release builds
|
||||
|
||||
Build the pinned environment with:
|
||||
|
||||
```sh
|
||||
docker build -f packaging/build/Dockerfile.glibc241 -t d4r-build:glibc241 packaging/build
|
||||
```
|
||||
|
||||
Inside that image, `scripts/build_release_glibc241.sh` rebuilds the GPU device helpers, ZLUDA and its LLVM, `d4r_emit`, the NGX shim, Wine CUDA bridge, patched vkd3d-proton, and performance/accuracy texture sets for every release target. Packaging then builds both network sets, checks all bundled Linux libraries against 2.41, and records the toolchain in `d4r/source/BUILD_INFO.txt`.
|
||||
|
||||
Mount the repository at `/work`, ROCm's compiler/headers/device libraries at `/opt/rocm`, and an official Rust toolchain (1.98.0 used for 0.1.3) at `/opt/rust`, with `/opt/rust/bin` on `PATH`. Keep toolchain and third-party runtime inputs read-only. Supply the normal package inputs listed above and these build settings:
|
||||
|
||||
| Variable | Input |
|
||||
|---|---|
|
||||
| `D4R_RELEASE_BUILD_ROOT` | writable directory under `/work/build/` |
|
||||
| `D4R_ZLUDA_SRC` | isolated checkout inside that directory, with both pinned LLVM and HiGHS submodules, the real OCKL LFS payload, and patches `0002`–`0007` applied |
|
||||
| `D4R_VKD3D_SRC` | isolated vkd3d-proton checkout inside that directory, with its submodules and patch `0001` applied |
|
||||
| `CARGO_HOME` | writable build-local Cargo cache; prefetch the locked dependencies for an offline build |
|
||||
| `D4R_ROCM_DIR` | `/opt/rocm` |
|
||||
| `D4R_ROCM_LINK_STUBS` | optional directory for additional ROCm link libraries |
|
||||
|
||||
Run `bash scripts/build_release_glibc241.sh` inside the container. The script checks that the build system actually reports `glibc 2.41`, rejects external source-cache checkouts, builds with the locked Cargo dependencies offline, and runs the configuration tests before packaging. The ZIP and checksum go in `$D4R_RELEASE_BUILD_ROOT/dist/`; logs and `toolchain.txt` remain in the build directory. AMD's bundled ROCm runtime, OptiScaler and NVIDIA's libraries remain supplied binaries; the Linux ABI check covers the bundled ROCm libraries too.
|
||||
|
||||
`D4R_BUNDLE_TEX` accepts the older flat directory for gfx1101, or a directory with per-target subdirectories (`gfx1100/`–`gfx1103/`, `gfx1200/`, `gfx1201/`, plus `gfx1200-fp8/` and `gfx1201-fp8/`). Build each texture set with `D4R_GPU_ARCH` and `D4R_ZLUDA_EMIT`; the `-fp8` sets also need `D4R_NATIVE_FP8=1`. `d4r_emit` targets those GPUs offline. Missing texture kernels fall back to ZLUDA on that target; the network-layer kernels are still included. Only the RX 7700 XT has been tested on real hardware.
|
||||
|
||||
## Checks
|
||||
|
||||
+10
-1
@@ -64,10 +64,16 @@ For ZLUDA-compiled code, compare rocjitsu runs with other rocjitsu runs: the emu
|
||||
|
||||
## Numerics
|
||||
|
||||
NVIDIA's tensor-core code rounds its f16 accumulator after every 16-deep step. The native kernels either do the same (bit-exact against the reference models) or keep f32 accumulators through a chain (`PWIN_F32ACC`, `SWIN_F32ACC`). The f32 version is more accurate than NVIDIA's own rounding, and its replayed output differs from the exact one by about 66 dB PSNR, which is invisible.
|
||||
The conservative kernels round their f16 accumulator after each MMA step (k16 for K, k32 for M). The fast kernels keep f32 accumulators through a chain (`PWIN_F32ACC`, `SWIN_F32ACC`); RDNA3 M also skips intermediate FP8 re-quantization (`SWIN_NO_Q8`). Wider arithmetic changes the network's intermediate values; it does not establish better image quality. Recorded fast-versus-conservative replays were close (about 66 dB PSNR), but that is not an RTX reference comparison or a guarantee for all scenes.
|
||||
|
||||
The installed K set uses f32 accumulation for enc0–enc2 and dec0–dec2 and exact rounding for the deep layers. The M set uses the fast numerics throughout.
|
||||
|
||||
**`[Kernels] PreferAccuracy = true`** (default `false`, environment `D4R_PREFER_ACCURACY=1`) selects a separate accuracy set for all K/M network layers and all texture/output variants, on every supported target, including gfx12 FP8. K disables `PWIN_F32ACC`; M restores FP8 quantization and rounds each k32 accumulator to f16. Texture builds use wave32 and retain the original denormal requirements; the existing exact round-half-away rewrite is retained. Native texture heads/tails already round their accumulators per k32 step. The bridge also disables `IgnoreDenormals`, translated f32 accumulator shadows, wave64 translation and NGX synchronization elision before ZLUDA loads, including when native kernels are off or fail their PTX hash check. Other interop and latency settings remain independent.
|
||||
|
||||
The bridge selects `kernels/accuracy/<target>` (or `<target>-fp8`). Accuracy directories carry a `d4r-accuracy.txt` marker written only after a successful build. A marked flat developer directory also works. Missing accuracy variants fall back to translated PTX and are logged; the bridge never substitutes fast native binaries. Restart the game when changing the setting. The mode uses a separate `d4r-accuracy` JIT cache under the configured cache directory so older runtimes cannot reuse experimental fast-math results. The first accuracy run may compile new kernels.
|
||||
|
||||
This mode aims to preserve NVIDIA's arithmetic, not to promise bit-identical RTX output: matrix accumulation order differs across hardware, and the shim still canonicalizes input formats and does not forward the optional transparency/current-color-bias masks. RTX parity requires identical captured inputs, library version, preset and temporal sequence on NVIDIA hardware.
|
||||
|
||||
## Building
|
||||
|
||||
```sh
|
||||
@@ -75,10 +81,13 @@ kernels/build.sh k # DLSS 4 layers (ROCm clang only)
|
||||
kernels/build.sh m # DLSS 4.5 layers
|
||||
kernels/build.sh tex # texture kernels (needs D4R_DLSS_DLL and D4R_ZLUDA_BUILD)
|
||||
kernels/build.sh all DIR # everything into DIR (default kernels/out/native)
|
||||
D4R_PREFER_ACCURACY=1 kernels/build.sh all DIR/accuracy # conservative versions of every family
|
||||
```
|
||||
|
||||
`D4R_GPU_ARCH` selects one target for this standalone build (default gfx1101). The release script builds the network layers for gfx1100–gfx1103 and gfx1200–gfx1201 by default and puts each set in its own directory. The network kernels need gfx11 or gfx12 WMMA. Texture-kernel builds use `D4R_ZLUDA_EMIT` to generate code objects for the selected target without that GPU. Set `D4R_NATIVE_FP8=1` on gfx12 for the matching FP8 M and texture variants.
|
||||
|
||||
The release includes both fast and accuracy network sets. Full releases also include accuracy texture sets: supply them in `D4R_BUNDLE_TEX/accuracy/<target>` or set `D4R_ZLUDA_EMIT` so packaging builds them. Build accuracy sets into a separate directory; the builder refuses to mark a directory containing unmarked older binaries as accurate.
|
||||
|
||||
## Validating a kernel
|
||||
|
||||
1. **Capture launches.** Set `D4R_CUDA_REPLAY_DUMP_DIR` (with `D4R_CUDA_REPLAY_DUMP_FILTER=<kernel name>`) while running the D3D12 harness or a game. The bridge then writes each matching launch as `manifest.txt`, `args.bin` and one `alloc-N.bin` per buffer.
|
||||
|
||||
+25
-3
@@ -10,15 +10,22 @@
|
||||
# D4R_NATIVE_FP8 1 (RDNA4 only): the variant for ZLUDA's native FP8 WMMA (d4r.ini [Kernels] NativeFp8):
|
||||
# M's layers on FP8 WMMA with NVIDIA's e4m3 activations, texture tails matching ZLUDA's
|
||||
# D4R_ZLUDA_WMMA_FP8_NATIVE lowering. K is the same in both variants.
|
||||
# D4R_PREFER_ACCURACY 1: preserve FP8 quantization, per-MMA f16 rounding and denormal handling;
|
||||
# build a separate set (default output: kernels/out/native/accuracy).
|
||||
# Texture kernels (tex) are NVIDIA's PTX with parts replaced, so they additionally need:
|
||||
# D4R_DLSS_DLL nvngx_dlss.dll 310.7 (its PTX is extracted into kernels/extracted/, never committed)
|
||||
# D4R_ZLUDA_EMIT ZLUDA's d4r_emit (patches/zluda applied; `cargo build --release -p ptx --example d4r_emit`),
|
||||
# which compiles PTX offline for D4R_GPU_ARCH (no GPU of that kind needed)
|
||||
# D4R_DLSS_PTX_DIR optional pre-extracted PTX directory for parallel per-target builds
|
||||
set -euo pipefail
|
||||
|
||||
HERE="$(cd "$(dirname "${BASH_SOURCE[0]}")" && pwd)"
|
||||
WHAT="${1:-all}"
|
||||
OUT="$(realpath -m "${2:-$HERE/out/native}")"
|
||||
ACCURACY="${D4R_PREFER_ACCURACY:-0}"
|
||||
[[ "$ACCURACY" == 0 || "$ACCURACY" == 1 ]] || { echo "D4R_PREFER_ACCURACY must be 0 or 1" >&2; exit 2; }
|
||||
DEFAULT_OUT="$HERE/out/native"
|
||||
[[ "$ACCURACY" == 1 ]] && DEFAULT_OUT+="/accuracy"
|
||||
OUT="$(realpath -m "${2:-$DEFAULT_OUT}")"
|
||||
ROCM="${D4R_ROCM_DIR:-/opt/rocm}"
|
||||
ARCH="${D4R_GPU_ARCH:-gfx1101}"
|
||||
FP8="${D4R_NATIVE_FP8:-0}"
|
||||
@@ -30,6 +37,14 @@ esac
|
||||
CLANG="$ROCM/lib/llvm/bin/clang++"
|
||||
[[ -x "$CLANG" ]] || { echo "clang++ not found in $ROCM/lib/llvm/bin (set D4R_ROCM_DIR)" >&2; exit 2; }
|
||||
mkdir -p "$OUT"
|
||||
case "$WHAT" in all|k|m|tex) ;; *) echo "unknown kernel family: $WHAT" >&2; exit 2 ;; esac
|
||||
# Never certify a directory containing older fast binaries as an accuracy set.
|
||||
if [[ "$ACCURACY" == 1 ]] && compgen -G "$OUT/*.hsaco" >/dev/null &&
|
||||
{ [[ ! -f "$OUT/d4r-accuracy.txt" ]] || [[ "$(cat "$OUT/d4r-accuracy.txt")" != 1 ]]; }; then
|
||||
echo "accuracy kernels need an empty output directory or an existing accuracy set: $OUT" >&2
|
||||
exit 2
|
||||
fi
|
||||
rm -f "$OUT/d4r-accuracy.txt"
|
||||
|
||||
# HIP source -> raw code object (the kernel name inside matches the DLSS kernel it replaces)
|
||||
build_hip() {
|
||||
@@ -39,6 +54,7 @@ build_hip() {
|
||||
tmp="$(mktemp -d)"
|
||||
# per-kernel compiler flags from a "// d4r-build-flags: ..." line in the source
|
||||
flags="$(sed -n 's|^// d4r-build-flags: *||p' "$src")"
|
||||
[[ "$ACCURACY" == 1 ]] && extra+=" -DD4R_ACCURACY"
|
||||
# shellcheck disable=SC2086
|
||||
(cd "$tmp" && "$CLANG" -x hip --offload-arch="$ARCH" --offload-device-only -O3 $flags $extra -I"$ROCM/include" \
|
||||
--rocm-path="$ROCM" --rocm-device-lib-path="$ROCM/amdgcn/bitcode" -I"$(dirname "$src")" \
|
||||
@@ -59,8 +75,12 @@ if [[ "$WHAT" == all || "$WHAT" == tex ]]; then
|
||||
echo "== texture kernels (NVIDIA PTX with native parts)"
|
||||
: "${D4R_DLSS_DLL:?set D4R_DLSS_DLL to nvngx_dlss.dll (310.7)}"
|
||||
: "${D4R_ZLUDA_EMIT:?set D4R_ZLUDA_EMIT to d4r_emit from a ZLUDA build with patches/zluda}"
|
||||
PTX_DIR="$HERE/extracted/ptx"
|
||||
PTX_DIR="${D4R_DLSS_PTX_DIR:-$HERE/extracted/ptx}"
|
||||
if [[ -z "${D4R_DLSS_PTX_DIR:-}" ]]; then
|
||||
python3 "$HERE/tools/extract_dlss_ptx.py" "$D4R_DLSS_DLL" "$PTX_DIR"
|
||||
elif [[ ! -d "$PTX_DIR" ]]; then
|
||||
echo "missing extracted PTX directory: $PTX_DIR" >&2; exit 2
|
||||
fi
|
||||
# kernel : source of its native part [: w64 = compiled as wave64 (two CUDA warps per wave; RDNA3 issues
|
||||
# FP32 work for all 64 lanes at once). Only for kernels without MMAs; measured faster, bit-identical:
|
||||
# post 0.89 -> 0.77 ms, hiluma output 0.905 -> 0.887 ms (downsample was slower as wave64).]
|
||||
@@ -84,8 +104,10 @@ if [[ "$WHAT" == all || "$WHAT" == tex ]]; then
|
||||
done
|
||||
for spec in "${specs[@]}"; do
|
||||
IFS=: read -r kernel src mode <<< "$spec"
|
||||
D4R_ZLUDA_WAVE64="$([[ "$mode" == w64 ]] && echo 1 || echo 0)" D4R_ROCM_DIR="$ROCM" D4R_GPU_ARCH="$ARCH" \
|
||||
D4R_PREFER_ACCURACY="$ACCURACY" \
|
||||
D4R_ZLUDA_WAVE64="$([[ "$mode" == w64 && "$ACCURACY" == 0 ]] && echo 1 || echo 0)" D4R_ROCM_DIR="$ROCM" D4R_GPU_ARCH="$ARCH" \
|
||||
D4R_TEX_FP8="$FP8" D4R_DLSS_PTX_DIR="$PTX_DIR" "$HERE/tex/build_tex.sh" "$kernel" "$src" "$OUT"
|
||||
done
|
||||
fi
|
||||
[[ "$ACCURACY" == 1 ]] && printf '1\n' > "$OUT/d4r-accuracy.txt"
|
||||
echo "native kernels in $OUT"
|
||||
@@ -10,6 +10,9 @@
|
||||
#include <hip/hip_runtime.h>
|
||||
#include <stdint.h>
|
||||
#include "../common/wmma_layout.h"
|
||||
#if defined(D4R_ACCURACY) && defined(PWIN_F32ACC)
|
||||
#undef PWIN_F32ACC
|
||||
#endif
|
||||
#pragma clang fp contract(off)
|
||||
|
||||
typedef _Float16 half_t;
|
||||
|
||||
@@ -9,6 +9,9 @@
|
||||
#include <hip/hip_runtime.h>
|
||||
#include <stdint.h>
|
||||
#include "../common/wmma_layout.h"
|
||||
#ifdef D4R_ACCURACY
|
||||
#define SWIN_EXACT
|
||||
#endif
|
||||
#if defined(D4R_FP8_WMMA) && D4R_WMMA_LAYOUT != 12 && defined(__AMDGCN__)
|
||||
#error "D4R_FP8_WMMA needs the gfx12 WMMA layout"
|
||||
#endif
|
||||
|
||||
@@ -11,12 +11,14 @@ D="$(cd "$(dirname "${BASH_SOURCE[0]}")" && pwd)"
|
||||
R="${D4R_ROCM_DIR:-/opt/rocm}"
|
||||
ARCH="${D4R_GPU_ARCH:-gfx1101}"
|
||||
FP8="${D4R_TEX_FP8:-0}"
|
||||
ACCURACY="${D4R_PREFER_ACCURACY:-0}"
|
||||
LLVM="$R/lib/llvm/bin"
|
||||
B="$(mktemp -d)"
|
||||
trap 'rm -rf "$B"' EXIT
|
||||
# D4R_TEX_CFLAGS: extra flags for SRC.hip (tests, e.g. -DD4R_WMMA_LAYOUT=12 for the gfx12-layout shim on gfx11)
|
||||
read -r -a FLAGS <<< "${D4R_TEX_CFLAGS:-}"
|
||||
[[ "$FP8" == 1 ]] && FLAGS+=(-DD4R_TEX_FP8)
|
||||
[[ "$ACCURACY" == 1 ]] && FLAGS+=(-DD4R_ACCURACY)
|
||||
# SRC.hip -> bitcode without target attributes, so ZLUDA's own target settings apply after linking
|
||||
"$LLVM/clang++" -x hip -std=c++20 -nogpuinc -nogpulib -O3 -mno-wavefrontsize64 --offload-device-only \
|
||||
--offload-arch="$ARCH" -fgpu-rdc -emit-llvm -c -Xclang -fdenormal-fp-math=dynamic -DD4R_KERNEL_NAME="$K" \
|
||||
@@ -24,10 +26,12 @@ read -r -a FLAGS <<< "${D4R_TEX_CFLAGS:-}"
|
||||
"$LLVM/llvm-dis" "$B/raw.bc" -o "$B/raw.ll"
|
||||
sed -E -e '/@llvm.used/d' -e '/wchar_size/d' -e '/llvm.module.flags/d' -e '/__hip_cuid/d' -e 's/optnone//g' \
|
||||
-e "s/\"target-cpu\"=\"$ARCH\"//g" -e 's/"target-features"="[^"]+"//g' "$B/raw.ll" | "$LLVM/llvm-as" -o "$B/extra.bc" -
|
||||
python3 "$D/make_ptx.py" "$K" "$B/$K.ptx" >/dev/null
|
||||
D4R_PREFER_ACCURACY="$ACCURACY" python3 "$D/make_ptx.py" "$K" "$B/$K.ptx" >/dev/null
|
||||
# the code-generation switches of the runtime (d4r.ini [Kernels]), which ZLUDA's module cache keys on
|
||||
env LD_LIBRARY_PATH="$R/lib" D4R_ZLUDA_EXTRA_BC="$B/extra.bc" D4R_ZLUDA_WMMA=1 D4R_ZLUDA_WMMA_FP8=1 \
|
||||
D4R_ZLUDA_WMMA_FP8_NATIVE="$FP8" D4R_ZLUDA_IGNORE_DENORMAL=1 D4R_ZLUDA_IMPLICIT_MAX_BLOCK=256 \
|
||||
D4R_ZLUDA_WAVE64="${D4R_ZLUDA_WAVE64:-0}" "$D4R_ZLUDA_EMIT" "$B/$K.ptx" "$B/dump" "$ARCH" >/dev/null
|
||||
D4R_ZLUDA_WMMA_FP8_NATIVE="$FP8" D4R_ZLUDA_IGNORE_DENORMAL="$((1 - ACCURACY))" \
|
||||
D4R_ZLUDA_WMMA_F32ACC=0 D4R_ZLUDA_FAST_MATH=0 D4R_ZLUDA_IMPLICIT_MAX_BLOCK=256 \
|
||||
D4R_ZLUDA_WAVE64="$([[ "$ACCURACY" == 1 ]] && echo 0 || echo "${D4R_ZLUDA_WAVE64:-0}")" \
|
||||
"$D4R_ZLUDA_EMIT" "$B/$K.ptx" "$B/dump" "$ARCH" >/dev/null
|
||||
cp "$B/dump/module.hsaco" "$OUT/$K.hsaco"
|
||||
printf '%-52s %s\n' "$K" "$(grep -E '^\s+\.(vgpr_count|private_segment_fixed_size|wavefront_size):' "$B/dump/asm.s" | tr -s ' ' | paste -sd' ')"
|
||||
@@ -14,7 +14,7 @@
|
||||
// Kernels that ZLUDA compiles in strict-FP mode (constrained intrinsics) cannot take inlined FP code from
|
||||
// here (the AMDGPU backend fails on some constrained operations): build them with -DD4R_SUST_OUTLINE,
|
||||
// which keeps the FP bodies of the surface stores in noinline leaf functions (no calls, no stack).
|
||||
#ifdef D4R_SUST_OUTLINE
|
||||
#if defined(D4R_SUST_OUTLINE) || defined(D4R_ACCURACY)
|
||||
#define FP_BODY __attribute__((device, noinline)) static
|
||||
#else
|
||||
#define FP_BODY __attribute__((device, always_inline)) static inline
|
||||
|
||||
@@ -58,6 +58,12 @@ compiled. They are cached in ~/.cache/d4r, so later starts are quick.
|
||||
|
||||
Settings
|
||||
--------
|
||||
- In d4r/d4r.ini, [Kernels] PreferAccuracy = true prioritizes fidelity over performance for every
|
||||
native kernel and the translated fallback. It selects separately built accuracy kernels, restores
|
||||
intermediate FP8 quantization and per-MMA f16 rounding, preserves denormal handling, and keeps
|
||||
NGX's synchronization calls. It defaults to false. Restart the game after changing it; the first
|
||||
start may compile a separate cache. Missing accuracy variants use translated kernels, never the
|
||||
fast native set. The mode aims to match NVIDIA's output, but 1:1 RTX image quality is not proven.
|
||||
- d4r/d4r.ini: d4r's settings for this game. The main one is the DLSS model:
|
||||
K (DLSS 4, default), E (DLSS 3 CNN, a little faster) or M (DLSS 4.5, slowest).
|
||||
- On RDNA4, [Kernels] NativeFp8 is on by default. It selects native FP8 WMMA and the matching
|
||||
|
||||
+44
-54
@@ -1,73 +1,63 @@
|
||||
# d4r 0.1.1
|
||||
# d4r 0.1.3
|
||||
|
||||
NVIDIA's own DLSS Super Resolution on AMD Radeon RX 7000 (RDNA3) GPUs, in DirectX 12 games under Proton. This release fixes a VRAM leak and two input-format problems, bundles the ROCm runtime, and adds a dozen tested games.
|
||||
This release adds an optional accuracy mode and fixes the GLIBC compatibility failure, DLSS artifacts, and stale output-buffer redirects reported after 0.1.2. Accuracy mode is **off by default**.
|
||||
|
||||
## What's new
|
||||
## Added
|
||||
|
||||
- **No more VRAM growth when changing the DLSS quality setting.** Each switch between Quality, Balanced, Performance and so on used to keep about 130 MB of VRAM until the game closed, because of a reference-counting bug in ROCm 7.2's external-memory mapping. d4r now reuses its shared buffers, and VRAM stays flat over repeated switches. It also no longer leaks a file handle per buffer.
|
||||
- **Games that pass 4-channel motion vectors now work.** Motion vectors in `R16G16B16A16` formats (including `TYPELESS`, as Dying Light: The Beast uses) used to be rejected, which left the screen black. They are now converted on the GPU and stay on the fast VRAM path.
|
||||
- **Multi-channel exposure textures stay on the VRAM path.** Games that pass exposure as an RGBA float texture no longer fall back to the slower copy through system memory, which showed up as reflections lagging behind (Ready or Not).
|
||||
- **ROCm no longer needs to be installed.** The zip includes the ROCm 7.2.4 runtime (HIP, HSA, comgr) in `d4r/rocm`, from AMD's Ubuntu 22.04 packages; it runs under Steam's container runtime on any distribution. `RocmDir` in `d4r/d4r.ini` still selects another installation.
|
||||
- **Prefer accuracy over performance.** Set `[Kernels] PreferAccuracy = true` in `d4r/d4r.ini` and restart the game. The release includes separate accuracy variants of every native network and texture kernel for all supported RDNA3 and RDNA4 targets, including RDNA4's native FP8 variants.
|
||||
- K restores FP16 accumulator rounding after each matrix step. M also restores intermediate FP8 quantization.
|
||||
- The accuracy path retains denormal handling, disables relaxed accumulation/fast-math switches, and keeps NGX's synchronization calls. It uses a separate compilation cache.
|
||||
- Missing accuracy variants use translated NVIDIA kernels and are logged; the fast native set is never silently substituted.
|
||||
- This aims to preserve NVIDIA's arithmetic. It is slower, its FPS cost has not been benchmarked, and **1:1 image quality against RTX DLSS is not proven**.
|
||||
- **Reproducible GLIBC 2.41 build environment.** A pinned Debian build image and release-build script rebuild ZLUDA/LLVM, the Wine bridge, the Windows DLLs, and both kernel sets. The ZIP includes toolchain details in `d4r/source/BUILD_INFO.txt`.
|
||||
|
||||
## Tested games
|
||||
## Fixed
|
||||
|
||||
Radeon RX 7700 XT, GE-Proton 11-3. All three DLSS models (E, K, M) run in each game:
|
||||
- **GLIBC loader compatibility ([#6](https://github.com/countervolts/d4r/issues/6)).** The previous release required `GLIBC_2.44` from `libm.so.6`, preventing ZLUDA from loading on systems such as the reporter's Bazzite installation. This release is built in a GLIBC 2.41 environment; the package check rejects any bundled Linux library requiring a newer ABI.
|
||||
- **Cyberpunk 2077 preset-K black artifacts ([#5](https://github.com/countervolts/d4r/issues/5)).** Preserve FP16/FP64 denormal requirements while limiting the performance optimization to FP32. The fix covers both translated kernels and the rebuilt native texture kernels. Captured-scene replays showed substantially fewer sky artifacts; this is not a guarantee that every scene is artifact-free.
|
||||
- **Stale direct-output redirects after resource destruction ([#8](https://github.com/countervolts/d4r/issues/8)).** Reused CUDA array handles no longer inherit an earlier feature's output buffer. This addresses the quality-switch corruption reported with preset M in Spider-Man 2.
|
||||
|
||||
SILENT HILL Townfall, Ghost of Tsushima DIRECTOR'S CUT, Ready or Not, Clair Obscur: Expedition 33, Marvel's Spider-Man: Miles Morales, The Last of Us Part I, Control Ultimate Edition, Cyberpunk 2077, Alan Wake 2, SILENT HILL 2 (2024), Subnautica 2, Horizon Zero Dawn Remastered, Ratchet & Clank: Rift Apart, Dying Light: The Beast.
|
||||
## Improved
|
||||
|
||||
Several need a small setup step: renaming a file, a launch option, or an `OptiScaler.ini` setting. [SUPPORTED_GAMES.md](https://github.com/countervolts/d4r/blob/main/SUPPORTED_GAMES.md) lists these, along with known image-quality issues per model.
|
||||
- **Synchronization diagnostics and an optional blocking output wait.** `D4R_SHIM_BLOCKING_SYNC=1` yields the CPU while waiting for DLSS output, with a fallback to context synchronization. It is an opt-in mitigation for [#7](https://github.com/countervolts/d4r/issues/7); reduced CPU usage on the reporter's RDNA4 setup still needs confirmation.
|
||||
- **More useful failure logs.** Rejected input/output formats and dimensions are now recorded even after startup, with repeated errors rate-limited. Output-wait CPU and wall time are reported separately, and GPU timing queries are deferred until asynchronous work finishes.
|
||||
- **More conservative accuracy texture builds.** Strict surface conversions use separate helper functions, avoiding a compiler failure when the original denormal handling is retained.
|
||||
- **Accuracy build safeguards.** The builder refuses to label a directory containing older fast binaries as an accuracy set. Configuration tests cover every release target, missing-set fallback, invalid markers, environment precedence, and the default-off behavior.
|
||||
|
||||
## Install
|
||||
## Also included from 0.1.2
|
||||
|
||||
1. Extract `d4r-0.1.1.zip` into the folder that holds the game's main `.exe`. For Unreal Engine games that is `<Project>/Binaries/Win64`. Keep the zip's layout: `dxgi.dll`, `OptiScaler.ini`, `d3d12.dll` and `d3d12core.dll` go next to the `.exe`, beside the `d4r` folder.
|
||||
2. In Steam, force GE-Proton 11 for the game, and set these launch options:
|
||||
These capabilities remain in the release; they are not newly validated hardware results:
|
||||
|
||||
- Experimental RDNA4 builds for gfx1200/gfx1201, with `NativeFp8` enabled by default, alongside gfx1100–gfx1103 RDNA3 builds.
|
||||
- Kernel selection uses the GPU with the most SIMDs when integrated and discrete GPUs coexist; `D4R_GPU_ARCH` overrides it.
|
||||
- DLSS 3 matrix-kernel acceleration; M's cached weight preparation, packed FP8 encoding, improved patch-merge/weight loads, and direct output; K's CU-mode layers; wave64 performance texture variants.
|
||||
- Native texture/output variants for the game's motion-vector resolution, HDR/LDR input and depth direction, compiled offline per GPU target.
|
||||
- The bundled ROCm 7.2.4 runtime: no separate ROCm installation is required.
|
||||
|
||||
The 0.1.2 performance measurements remain historical results. They are not benchmarks of this rebuild or the new accuracy mode.
|
||||
|
||||
## Install or upgrade
|
||||
|
||||
1. Back up your `d4r/d4r.ini` and `OptiScaler.ini` if you customized them.
|
||||
2. Extract `d4r-0.1.3.zip` into the folder holding the game's main `.exe` (`<Project>/Binaries/Win64` for Unreal Engine games), keeping the ZIP's layout.
|
||||
3. Restore your settings if needed. Older INIs omit `PreferAccuracy`, which defaults to off; add it under `[Kernels]` to enable it.
|
||||
4. Select GE-Proton 11 in Steam (tested integration: GE-Proton11-3), with:
|
||||
```
|
||||
PROTON_FORCE_NVAPI=1 DXVK_NVAPI_GPU_ARCH=AD100 %command%
|
||||
```
|
||||
3. Select DLSS in the game. The first start compiles DLSS's GPU kernels, which takes about a minute and a half; later starts use the cache in `~/.cache/d4r`.
|
||||
5. Select DLSS in the game and restart after changing the accuracy option.
|
||||
|
||||
**Upgrading from 0.1.0:** extract over the old files, then restore your `d4r/d4r.ini` if you changed it. `D4R_README.txt` in the zip has the details, and `sh d4r/d4r-check.sh` checks an install.
|
||||
The rebuilt runtime may compile a new kernel cache on first start. `sh d4r/d4r-check.sh` checks the install. [SUPPORTED_GAMES.md](https://github.com/countervolts/d4r/blob/main/SUPPORTED_GAMES.md) lists game-specific setup and known issues.
|
||||
|
||||
## Requirements
|
||||
## Validation and limits
|
||||
|
||||
- An AMD Radeon RX 7000 series GPU. The fast kernels are built for gfx1101 (RX 7700 XT, RX 7800 XT, RX 7700). Other RDNA3 cards run DLSS without them:
|
||||
- DLSS 3 (E) at full speed;
|
||||
- DLSS 4.5 (M) at about half speed;
|
||||
- DLSS 4 (K) without its transformer, with a worse image.
|
||||
- The amdgpu kernel driver (`/dev/kfd`).
|
||||
- GE-Proton 11 (tested: GE-Proton11-3).
|
||||
|
||||
## Performance
|
||||
|
||||
Radeon RX 7700 XT, SILENT HILL Townfall at 2560×1440, average fps over the same 62-second walk:
|
||||
|
||||
| Mode | DLSS 3 CNN (E) | DLSS 4 (K) | DLSS 4.5 (M) | FSR 4 |
|
||||
|---|---|---|---|---|
|
||||
| Quality | 72 | 69 | 51 | 76 |
|
||||
| Balanced | 80 | 76 | 59 | 84 |
|
||||
| Performance | 88 | 82 | 69 | 94 |
|
||||
| Ultra Performance | 89 | 93 | 90 | 107 |
|
||||
|
||||
Native 2560×1440 without upscaling (the game's TSR at 100%) runs at 49 fps. This release does not change the per-frame cost of DLSS.
|
||||
|
||||
## Known limitations
|
||||
|
||||
- Only DLSS Super Resolution in DirectX 12 games. There is no Frame Generation or Ray Reconstruction: keep Ray Reconstruction off in games that offer it.
|
||||
- Use the game's DLSS setting where it exists. Feeding DLSS from FSR or XeSS inputs through OptiScaler can ghost, or show a black screen in some games.
|
||||
- Saving from the OptiScaler overlay ("Save INI") resets d4r's `OptiScaler.ini` values to `auto`, including frame generation. Restore them afterwards.
|
||||
- Do not use it in games with anti-cheat.
|
||||
- DLSS 4.5 (M) is much slower than FSR 4 on RDNA3.
|
||||
- All bundled Linux ELF libraries are checked against the GLIBC 2.41 ABI limit; release loading is checked inside that environment.
|
||||
- The release contains performance and accuracy kernels for all eight target variants. Configuration tests and sampled CPU-emulated kernel/reference checks cover the new accuracy path; these do not establish full-game or RTX parity.
|
||||
- RDNA4 remains experimental: emulator/compiler coverage does not prove hardware speed, image quality, or driver stability. The external RX 7900 XTX report is RDNA3, not RDNA4 validation.
|
||||
- Super Resolution only: Frame Generation, Ray Reconstruction, and DLSS 5 Neural Rendering are unsupported. Keep Ray Reconstruction off.
|
||||
|
||||
## Licenses
|
||||
|
||||
d4r is Apache 2.0. The zip also contains:
|
||||
- ZLUDA (Apache 2.0 or MIT);
|
||||
- vkd3d-proton (LGPL 2.1, patched; the patch is in `d4r/source`);
|
||||
- the ROCm 7.2.4 runtime, unmodified: HIP and rocprofiler-register (MIT), ROCr (NCSA), comgr (Apache 2.0), and Ubuntu's libelf and libnuma (LGPL). The license texts are in `d4r/licenses`;
|
||||
- OptiScaler 0.9.4 (GPL 3.0, unmodified; source at https://github.com/optiscaler/OptiScaler/tree/v0.9.4).
|
||||
d4r is Apache 2.0. ZLUDA, LLVM, vkd3d-proton, OptiScaler, and the bundled ROCm libraries retain their respective licenses in `d4r/licenses`; sources and patches are listed in `d4r/source`. NVIDIA's libraries and texture kernels compiled from its code are not covered by those licenses. d4r is not affiliated with NVIDIA or AMD.
|
||||
|
||||
`d4r/source/SOURCES.txt` lists where every file comes from.
|
||||
|
||||
NVIDIA's files in the zip, and the kernels built from NVIDIA's code, belong to NVIDIA and are not covered by any of these licenses. d4r is not affiliated with NVIDIA, AMD or the OptiScaler project.
|
||||
|
||||
**SHA-256** `d4r-0.1.1.zip`: `@SHA256@`
|
||||
The attached `.sha256` file contains the ZIP's checksum.
|
||||
@@ -4,13 +4,13 @@ d4r @VERSION@: where every file in this release comes from
|
||||
Built from source by d4r (Apache License 2.0, d4r/licenses/d4r-LICENSE.txt):
|
||||
d4r/nvngx.dll NGX shim tools/d4r_nvngx_shim.cpp in the d4r repository
|
||||
d4r/nvcuda.dll Wine CUDA bridge tools/wine_nvcuda_bridge.c
|
||||
d4r/kernels/ native RDNA3 kernels for the DLSS 4 and 4.5 network layers, kernels/k and kernels/m
|
||||
d4r/kernels/ native RDNA3/RDNA4 kernels for the DLSS 4 and 4.5 network layers, kernels/k and kernels/m
|
||||
(d4r-kernels.txt lists hashes of the DLSS code each kernel replaces; it holds no NVIDIA code)
|
||||
d4r/d4r.ini, d4r/d4r-check.sh, D4R_README.txt
|
||||
|
||||
Third-party software, unmodified or patched by d4r:
|
||||
d4r/zluda/libcuda.so ZLUDA (Apache License 2.0 or MIT), https://github.com/vosen/ZLUDA
|
||||
commit @ZLUDA_COMMIT@ with d4r/source/patches/zluda/0002 to 0005 applied.
|
||||
commit @ZLUDA_COMMIT@ with d4r/source/patches/zluda/0002 to 0007 applied.
|
||||
It contains LLVM (Apache License 2.0 with LLVM exceptions).
|
||||
Licenses: d4r/licenses/ZLUDA-LICENSE-*.txt, d4r/licenses/LLVM-LICENSE.txt
|
||||
d3d12.dll, d3d12core.dll
|
||||
|
||||
+1
-1
@@ -1 +1 @@
|
||||
0.1.2
|
||||
0.1.3
|
||||
@@ -0,0 +1,19 @@
|
||||
FROM debian:trixie-slim@sha256:a99cfc517144bc59b1978475ec53b46ecabec7e43635402ee5b77cc54cd1b20a
|
||||
|
||||
RUN apt-get update && DEBIAN_FRONTEND=noninteractive apt-get install -y --no-install-recommends \
|
||||
build-essential clang cmake ninja-build pkg-config libssl-dev python3 python3-numpy \
|
||||
git git-lfs wine64-tools libwine-dev gcc-mingw-w64-x86-64-posix \
|
||||
g++-mingw-w64-x86-64-posix meson libvulkan-dev zip unzip ca-certificates \
|
||||
&& rm -rf /var/lib/apt/lists/*
|
||||
|
||||
# ROCm loads the system's AMD DRM library even for the CPU-only loader check.
|
||||
RUN apt-get update && DEBIAN_FRONTEND=noninteractive apt-get install -y --no-install-recommends \
|
||||
libdrm-amdgpu1 libdrm2 mingw-w64-tools glslang-tools spirv-tools \
|
||||
&& rm -rf /var/lib/apt/lists/*
|
||||
|
||||
RUN ln -s /usr/lib/wine/winegcc /usr/local/bin/winegcc \
|
||||
&& ln -s /usr/lib/wine/winebuild /usr/local/bin/winebuild \
|
||||
&& ln -s /usr/bin/clang-19 /usr/local/bin/clang-cl \
|
||||
&& useradd --uid 1000 --create-home builder
|
||||
USER builder
|
||||
WORKDIR /work
|
||||
@@ -21,6 +21,10 @@ ShowWatermark = false
|
||||
FrameAge = 0
|
||||
|
||||
[Kernels]
|
||||
; Prioritize fidelity over speed. Uses accuracy variants of all native kernels, preserves NVIDIA's
|
||||
; intermediate FP8/f16 rounding and denormal handling, and keeps NGX's synchronization calls.
|
||||
; Slower but aims to match RTX DLSS.
|
||||
PreferAccuracy = false
|
||||
; Hand-written RDNA3 and RDNA4 kernels for the DLSS 4 and 4.5 networks (d4r\kernels). Each one is used
|
||||
; only when your DLSS library's code for that kernel matches the code it was written for; otherwise
|
||||
; that kernel is compiled from NVIDIA's code instead, which is slower but still correct.
|
||||
@@ -55,3 +59,5 @@ Profile = false
|
||||
|
||||
[Env]
|
||||
; Extra environment variables for d4r, NAME = value.
|
||||
; Use a blocking CUDA event while waiting for DLSS output.
|
||||
; D4R_SHIM_BLOCKING_SYNC = 1
|
||||
@@ -1225,9 +1225,10 @@ index e6f22a6..4256ae5 100644
|
||||
Kernel(SpirvWord),
|
||||
}
|
||||
|
||||
+// d4r: D4R_ZLUDA_IGNORE_DENORMAL=1 drops per-instruction denormal (.ftz) requirements, so a kernel
|
||||
+// keeps one denormal mode instead of switching it around ftz instructions (differences only for
|
||||
+// values below ~1e-38). Not part of the JIT cache key: use a fresh cache when toggling it.
|
||||
+// d4r: D4R_ZLUDA_IGNORE_DENORMAL=1 drops only FP32 denormal (.ftz) requirements to avoid mode switches.
|
||||
+// Keep FP16/FP64 requirements: flushing FP16 values below 2^-14 corrupts K's output and can make its
|
||||
+// translated attention layers non-finite. The runtime fingerprints code-generation switches in the
|
||||
+// JIT cache key; native texture code objects must also be rebuilt after changing this policy.
|
||||
+fn ignore_denormal_modes() -> bool {
|
||||
+ static VALUE: std::sync::OnceLock<bool> = std::sync::OnceLock::new();
|
||||
+ *VALUE.get_or_init(|| std::env::var("D4R_ZLUDA_IGNORE_DENORMAL").map_or(false, |v| v.trim() == "1"))
|
||||
@@ -1237,7 +1238,6 @@ index e6f22a6..4256ae5 100644
|
||||
+ let mut modes = get_modes_inner(inst);
|
||||
+ if ignore_denormal_modes() {
|
||||
+ modes.denormal_f32 = None;
|
||||
+ modes.denormal_f16f64 = None;
|
||||
+ }
|
||||
+ // d4r: D4R_ZLUDA_DEBUG_MODES=1 prints instructions that need a non-default rounding mode
|
||||
+ if std::env::var("D4R_ZLUDA_DEBUG_MODES").map_or(false, |v| v == "1") {
|
||||
|
||||
@@ -16,7 +16,7 @@ ln -sfn "$VULKAN_INCLUDE/vulkan" "$ROOT/build/vulkan-include/vulkan"
|
||||
ln -sfn "$VULKAN_INCLUDE/vk_video" "$ROOT/build/vulkan-include/vk_video"
|
||||
PARAM_OBJECT="$ROOT/build/d4r_ngx_param_msvc.obj"
|
||||
"$CLANG_CL" --target=x86_64-pc-windows-msvc /nologo /std:c++20 /O2 /c /GS- /GR- /EHs-c- /Zl \
|
||||
"/Fo$PARAM_OBJECT" "$ROOT/tools/d4r_ngx_param_msvc.cpp"
|
||||
"/Fo$PARAM_OBJECT" -- "$ROOT/tools/d4r_ngx_param_msvc.cpp"
|
||||
"$MINGW_CXX" -std=c++20 -O2 -Wall -Wextra -Wno-missing-field-initializers -I"$ROOT/build/vulkan-include" -shared -static -static-libgcc -static-libstdc++ \
|
||||
"$ROOT/tools/d4r_nvngx_shim.cpp" "$ROOT/tools/d4r_ngx_param_host.cpp" "$PARAM_OBJECT" \
|
||||
-o "$ROOT/build/d4r_nvngx.dll"
|
||||
|
||||
Executable
+111
@@ -0,0 +1,111 @@
|
||||
#!/usr/bin/env bash
|
||||
# Run inside packaging/build/Dockerfile.glibc241 with a recent official Rust toolchain and ROCm mounted.
|
||||
# Supply isolated, patched ZLUDA/vkd3d checkouts and the usual package_release.sh inputs.
|
||||
set -euo pipefail
|
||||
ROOT="$(cd "$(dirname "${BASH_SOURCE[0]}")/.." && pwd)"
|
||||
: "${D4R_RELEASE_BUILD_ROOT:?set the build output directory}"
|
||||
: "${D4R_ZLUDA_SRC:?set a build-local ZLUDA checkout with patches 0002-0007 applied}"
|
||||
: "${D4R_VKD3D_SRC:?set a build-local vkd3d-proton checkout with patch 0001 applied}"
|
||||
: "${D4R_ROCM_DIR:?set ROCm with clang and device libraries}"
|
||||
BUILD="$(realpath -m "$D4R_RELEASE_BUILD_ROOT")"
|
||||
[[ "$(getconf GNU_LIBC_VERSION)" == 'glibc 2.41' ]] || {
|
||||
echo "This release build requires GLIBC 2.41; use the pinned Debian build image" >&2; exit 2;
|
||||
}
|
||||
# Helper generation modifies its source checkout. Refuse the external source-cache directory.
|
||||
case "$(realpath "$D4R_ZLUDA_SRC")" in "$BUILD"/*) ;; *) echo "ZLUDA source must be inside $BUILD" >&2; exit 2 ;; esac
|
||||
case "$(realpath "$D4R_VKD3D_SRC")" in "$BUILD"/*) ;; *) echo "vkd3d source must be inside $BUILD" >&2; exit 2 ;; esac
|
||||
mkdir -p "$BUILD/logs"
|
||||
for source in "$D4R_ZLUDA_SRC/ext/llvm-project/llvm/CMakeLists.txt" "$D4R_ZLUDA_SRC/ext/HiGHS/CMakeLists.txt"; do
|
||||
[[ -f "$source" ]] || { echo "missing pinned source submodule: $source" >&2; exit 2; }
|
||||
done
|
||||
export CARGO_TARGET_DIR="$BUILD/zluda-target"
|
||||
export CARGO_BUILD_JOBS="${CARGO_BUILD_JOBS:-8}"
|
||||
export CMAKE_BUILD_PARALLEL_LEVEL="$CARGO_BUILD_JOBS"
|
||||
export LIBRARY_PATH="$D4R_ROCM_DIR/lib${D4R_ROCM_LINK_STUBS:+:$D4R_ROCM_LINK_STUBS}"
|
||||
export LD_LIBRARY_PATH="$D4R_ROCM_DIR/lib"
|
||||
export HIP_PATH="$D4R_ROCM_DIR"
|
||||
export ROCM_PATH="$D4R_ROCM_DIR"
|
||||
export HIP_CLANG_PATH="$D4R_ROCM_DIR/lib/llvm/bin"
|
||||
{
|
||||
getconf GNU_LIBC_VERSION
|
||||
rustc --version
|
||||
cargo --version
|
||||
gcc --version | head -1
|
||||
winegcc --version | head -1
|
||||
"$D4R_ROCM_DIR/lib/llvm/bin/clang++" --version | head -1
|
||||
} > "$BUILD/toolchain.txt"
|
||||
|
||||
ZLUDA_SOURCE_ROOT="$D4R_ZLUDA_SRC" ROCM_ROOT="$D4R_ROCM_DIR" \
|
||||
D4R_ZLUDA_PTX_HELPER_WORK="$BUILD/helpers" "$ROOT/scripts/build_zluda_ptx_helpers.sh" \
|
||||
> "$BUILD/logs/helpers.log" 2>&1
|
||||
echo 'Device helpers rebuilt'
|
||||
(cd "$D4R_ZLUDA_SRC" && cargo build --offline --locked --release -p zluda \
|
||||
&& cargo build --offline --locked --release -p ptx --example d4r_emit) \
|
||||
> "$BUILD/logs/zluda.log" 2>&1
|
||||
export D4R_ZLUDA_DIR="$CARGO_TARGET_DIR/release"
|
||||
export D4R_ZLUDA_EMIT="$D4R_ZLUDA_DIR/examples/d4r_emit"
|
||||
"$ROOT/scripts/check_glibc_compat.sh" 2.41 "$D4R_ZLUDA_DIR/libnvcuda.so"
|
||||
echo 'ZLUDA and the offline emitter rebuilt; GLIBC check passed'
|
||||
# A minimal ROCm compiler extraction may omit lld. Use the matching LLVM built above so
|
||||
# all GPU targets link with the same AMDGPU/ELF support, inside the compatible environment.
|
||||
for llvm_build in "$CARGO_TARGET_DIR"/release/build/llvm_zluda-*/out/build; do
|
||||
[[ -f "$llvm_build/build.ninja" ]] || continue
|
||||
ninja -j "$CARGO_BUILD_JOBS" -C "$llvm_build" lld > "$BUILD/logs/lld.log" 2>&1
|
||||
export PATH="$llvm_build/bin:$PATH"
|
||||
break
|
||||
done
|
||||
command -v lld >/dev/null || { echo 'missing AMDGPU linker' >&2; exit 2; }
|
||||
|
||||
"$ROOT/scripts/build_d4r_nvngx_shim.sh" > "$BUILD/logs/shim.log" 2>&1
|
||||
"$ROOT/scripts/build_wine_nvcuda_bridge.sh" > "$BUILD/logs/bridge.log" 2>&1
|
||||
"$ROOT/scripts/check_glibc_compat.sh" 2.41 "$ROOT/build/wine-nvcuda/x86_64-unix/nvcuda.dll.so"
|
||||
if [[ ! -f "$BUILD/vkd3d-build/build.ninja" ]]; then
|
||||
meson setup --cross-file "$D4R_VKD3D_SRC/build-win64.txt" --buildtype release \
|
||||
-Denable_tests=false "$BUILD/vkd3d-build" "$D4R_VKD3D_SRC" > "$BUILD/logs/vkd3d.log" 2>&1
|
||||
fi
|
||||
ninja -j "$CARGO_BUILD_JOBS" -C "$BUILD/vkd3d-build" >> "$BUILD/logs/vkd3d.log" 2>&1
|
||||
export D4R_VKD3D_DIR="$BUILD/vkd3d"
|
||||
mkdir -p "$D4R_VKD3D_DIR"
|
||||
x86_64-w64-mingw32-strip -o "$D4R_VKD3D_DIR/d3d12.dll" "$BUILD/vkd3d-build/libs/d3d12/d3d12.dll"
|
||||
x86_64-w64-mingw32-strip -o "$D4R_VKD3D_DIR/d3d12core.dll" "$BUILD/vkd3d-build/libs/d3d12core/d3d12core.dll"
|
||||
echo 'Shim, bridge and vkd3d-proton rebuilt'
|
||||
|
||||
export D4R_BUNDLE_TEX="$BUILD/kernels"
|
||||
export D4R_DLSS_PTX_DIR="$BUILD/ptx"
|
||||
python3 "$ROOT/kernels/tools/extract_dlss_ptx.py" "$D4R_BUNDLE_DLSS" "$D4R_DLSS_PTX_DIR" > "$BUILD/logs/extract.log"
|
||||
build_textures() {
|
||||
local arch="$1" folder fp8 accuracy out
|
||||
folders=("$arch")
|
||||
[[ "$arch" == gfx12* ]] && folders+=("$arch-fp8")
|
||||
for folder in "${folders[@]}"; do
|
||||
fp8=0
|
||||
[[ "$folder" == *-fp8 ]] && fp8=1
|
||||
for accuracy in 0 1; do
|
||||
out="$D4R_BUNDLE_TEX/$folder"
|
||||
[[ "$accuracy" == 1 ]] && out="$D4R_BUNDLE_TEX/accuracy/$folder"
|
||||
D4R_PREFER_ACCURACY="$accuracy" D4R_GPU_ARCH="$arch" D4R_NATIVE_FP8="$fp8" \
|
||||
D4R_DLSS_DLL="$D4R_BUNDLE_DLSS" "$ROOT/kernels/build.sh" tex "$out" \
|
||||
> "$BUILD/logs/tex-$folder-$accuracy.log" 2>&1
|
||||
echo "Texture kernels rebuilt: $folder accuracy=$accuracy"
|
||||
done
|
||||
done
|
||||
}
|
||||
pending=()
|
||||
failed=0
|
||||
for arch in ${D4R_GPU_ARCHS:-gfx1100 gfx1101 gfx1102 gfx1103 gfx1200 gfx1201}; do
|
||||
build_textures "$arch" &
|
||||
pending+=("$!")
|
||||
if (( ${#pending[@]} >= 4 )); then
|
||||
wait "${pending[0]}" || failed=1
|
||||
pending=("${pending[@]:1}")
|
||||
fi
|
||||
done
|
||||
for pid in "${pending[@]}"; do wait "$pid" || failed=1; done
|
||||
[[ "$failed" == 0 ]] || { echo 'Texture target build failed' >&2; exit 1; }
|
||||
python3 -m unittest discover -s "$ROOT/tests" -v > "$BUILD/logs/tests.log" 2>&1
|
||||
export D4R_SKIP_BUILD=1
|
||||
export D4R_MAX_GLIBC=2.41
|
||||
export D4R_BUILD_INFO="$BUILD/toolchain.txt"
|
||||
export D4R_PACKAGE_KERNEL_JOBS=4
|
||||
"$ROOT/scripts/package_release.sh" "$BUILD/dist" > "$BUILD/logs/package.log" 2>&1
|
||||
echo "Release packaged in $BUILD/dist"
|
||||
@@ -28,6 +28,7 @@ mkdir -p "$WORK_ROOT"
|
||||
SOURCE="$ZLUDA_SOURCE_ROOT/ptx/lib/zluda_ptx_impl.cpp"
|
||||
PTX_LIB="$ZLUDA_SOURCE_ROOT/ptx/lib"
|
||||
COMMON_FLAGS=(-DHIP_ENABLE_WARP_SYNC_BUILTINS -std=c++20 -Xclang -fdenormal-fp-math=dynamic
|
||||
--rocm-path="$ROCM_ROOT" -I"$ROCM_ROOT/include"
|
||||
-Wall -Wextra -Wsign-compare -Wconversion -x hip "$SOURCE" -nogpulib -O3
|
||||
-mno-wavefrontsize64 --offload-device-only --offload-arch=gfx1030 -emit-llvm -c
|
||||
-Xclang -mlink-bitcode-file -Xclang "$OCML" "${EXTRA_FLAGS[@]}")
|
||||
|
||||
Executable
+32
@@ -0,0 +1,32 @@
|
||||
#!/usr/bin/env bash
|
||||
# Reject Linux release libraries that need a newer GLIBC than the target runtime.
|
||||
# Usage: check_glibc_compat.sh MAX_GLIBC LIBRARY [LIBRARY ...]
|
||||
set -euo pipefail
|
||||
|
||||
if [[ $# -lt 2 || ! "$1" =~ ^[0-9]+\.[0-9]+$ ]]; then
|
||||
printf 'usage: %s MAX_GLIBC LIBRARY [LIBRARY ...]\n' "$0" >&2
|
||||
exit 2
|
||||
fi
|
||||
max="GLIBC_$1"
|
||||
shift
|
||||
command -v readelf >/dev/null || { echo 'readelf is required to check GLIBC compatibility' >&2; exit 2; }
|
||||
|
||||
failed=0
|
||||
for library in "$@"; do
|
||||
if [[ ! -f "$library" ]]; then
|
||||
printf 'missing library: %s\n' "$library" >&2
|
||||
failed=1
|
||||
continue
|
||||
fi
|
||||
if ! versions="$(readelf -W --version-info "$library" 2>&1)"; then
|
||||
printf 'cannot inspect %s: %s\n' "$library" "$versions" >&2
|
||||
failed=1
|
||||
continue
|
||||
fi
|
||||
required="$(printf '%s\n' "$versions" | grep -Eo 'GLIBC_[0-9]+\.[0-9]+' | sort -Vu | tail -1 || true)"
|
||||
if [[ -n "$required" && "$(printf '%s\n%s\n' "$max" "$required" | sort -Vu | tail -1)" != "$max" ]]; then
|
||||
printf '%s requires %s (target: at most %s)\n' "$library" "$required" "$max" >&2
|
||||
failed=1
|
||||
fi
|
||||
done
|
||||
exit "$failed"
|
||||
@@ -75,6 +75,7 @@ def main(argv):
|
||||
return
|
||||
|
||||
env = {}
|
||||
env["D4R_PREFER_ACCURACY"] = "1" if flag("Kernels", "PreferAccuracy") else "0"
|
||||
|
||||
model = get("DLSS", "Model")
|
||||
if model is not None:
|
||||
|
||||
@@ -13,18 +13,24 @@
|
||||
# D4R_ROCM_DIR ROCm with clang, for the kernels default /opt/rocm
|
||||
# D4R_ROCM_RUNTIME ROCm runtime bundled as d4r/rocm (scripts/fetch_rocm_runtime.sh)
|
||||
# default ~/.cache/d4r-rocm-runtime
|
||||
# D4R_MAX_GLIBC highest GLIBC ABI the Linux libraries may require default 2.41
|
||||
# D4R_GPU_ARCHS GPU targets to build kernels for default gfx1100 gfx1101 gfx1102 gfx1103 gfx1200 gfx1201
|
||||
# (RDNA4 targets also get a <target>-fp8 folder: the kernels for d4r.ini NativeFp8 = on)
|
||||
# D4R_OPTISCALER_LICENSE OptiScaler's LICENSE (GPL-3.0) text; default: the system's SPDX copy
|
||||
# D4R_VKD3D_SRC vkd3d-proton source checkout, for its license files default ~/.cache/d4r-vkd3d-proton
|
||||
# D4R_ZLUDA_SRC ZLUDA source checkout, for its license files default: D4R_ZLUDA_DIR's ../d4r-zluda-upstream
|
||||
# SOURCE_DATE_EPOCH timestamp given to every packaged file default: the last commit's
|
||||
# D4R_BUILD_INFO optional build-toolchain/provenance text to include in d4r/source/
|
||||
# D4R_PACKAGE_KERNEL_JOBS independent target builds at once (default 1)
|
||||
# The zip also contains NVIDIA's files and the texture kernels built from NVIDIA's PTX; redistributing
|
||||
# those is up to whoever publishes it (they are not covered by d4r's license):
|
||||
# D4R_BUNDLE_DLSS nvngx_dlss.dll to include D4R_BUNDLE_NGX _nvngx.dll to include
|
||||
# D4R_BUNDLE_TEX directory with texture-kernel code objects (kernels/build.sh tex), one subdirectory
|
||||
# per target folder (gfx1101, gfx1201, gfx1201-fp8, ...), or a flat gfx1101 directory for
|
||||
# older builds
|
||||
# Accuracy texture sets go in accuracy/<target>/, built with D4R_PREFER_ACCURACY=1.
|
||||
# D4R_ZLUDA_EMIT d4r_emit from the patched ZLUDA build; required in full builds when an accuracy
|
||||
# texture set is not supplied in D4R_BUNDLE_TEX/accuracy/<target>.
|
||||
# D4R_BUNDLE_NVIDIA=0 leaves them out (d4r-VERSION-nonvidia.zip; users then add the two DLLs themselves).
|
||||
set -euo pipefail
|
||||
|
||||
@@ -101,6 +107,8 @@ cp "$ROOT/build/d4r_nvngx.dll" "$STAGE/d4r/nvngx.dll"
|
||||
cp "$ROOT/build/wine-nvcuda/x86_64-unix/nvcuda.dll.so" "$STAGE/d4r/nvcuda.dll"
|
||||
cp "$ZLUDA/libnvcuda.so" "$STAGE/d4r/zluda/libcuda.so"
|
||||
cp -r "$ROCM_RUNTIME/lib" "$STAGE/d4r/rocm/lib"
|
||||
"$ROOT/scripts/check_glibc_compat.sh" "${D4R_MAX_GLIBC:-2.41}" \
|
||||
"$STAGE/d4r/nvcuda.dll" "$STAGE/d4r/zluda/libcuda.so" "$STAGE/d4r/rocm/lib/"*
|
||||
cp "$ROOT/packaging/d4r.ini" "$STAGE/d4r/d4r.ini"
|
||||
cp "$ROOT/packaging/d4r-check.sh" "$STAGE/d4r/d4r-check.sh"
|
||||
if [[ "$VARIANT" == full ]]; then
|
||||
@@ -118,12 +126,13 @@ for arch in $ARCHS; do
|
||||
folders+=("$arch")
|
||||
[[ "$arch" == gfx12* ]] && folders+=("$arch-fp8")
|
||||
done
|
||||
for folder in "${folders[@]}"; do
|
||||
build_target() {
|
||||
local folder="$1" arch fp8 tex_dir accurate accurate_tex f
|
||||
arch="${folder%-fp8}"
|
||||
fp8=0
|
||||
[[ "$folder" == *-fp8 ]] && fp8=1
|
||||
D4R_ROCM_DIR="$ROCM" D4R_GPU_ARCH="$arch" D4R_NATIVE_FP8="$fp8" "$ROOT/kernels/build.sh" k "$STAGE/d4r/kernels/$folder" >/dev/null
|
||||
D4R_ROCM_DIR="$ROCM" D4R_GPU_ARCH="$arch" D4R_NATIVE_FP8="$fp8" "$ROOT/kernels/build.sh" m "$STAGE/d4r/kernels/$folder" >/dev/null
|
||||
D4R_PREFER_ACCURACY=0 D4R_ROCM_DIR="$ROCM" D4R_GPU_ARCH="$arch" D4R_NATIVE_FP8="$fp8" "$ROOT/kernels/build.sh" k "$STAGE/d4r/kernels/$folder" >/dev/null
|
||||
D4R_PREFER_ACCURACY=0 D4R_ROCM_DIR="$ROCM" D4R_GPU_ARCH="$arch" D4R_NATIVE_FP8="$fp8" "$ROOT/kernels/build.sh" m "$STAGE/d4r/kernels/$folder" >/dev/null
|
||||
rm -f "$STAGE/d4r/kernels/$folder"/*.resolution.txt # empty LTO notes from clang's -save-temps
|
||||
if [[ "$VARIANT" == full ]]; then
|
||||
tex_dir=""
|
||||
@@ -140,7 +149,49 @@ for folder in "${folders[@]}"; do
|
||||
fi
|
||||
fi
|
||||
python3 "$ROOT/kernels/tools/kernel_manifest.py" "$STAGE/d4r/kernels/$folder" "${DLLS[@]}"
|
||||
|
||||
# Every release target also gets conservative network and texture variants. Do not copy fast
|
||||
# texture objects into this set: their compiler policy is fixed inside the binary.
|
||||
accurate="$STAGE/d4r/kernels/accuracy/$folder"
|
||||
D4R_PREFER_ACCURACY=1 D4R_ROCM_DIR="$ROCM" D4R_GPU_ARCH="$arch" D4R_NATIVE_FP8="$fp8" "$ROOT/kernels/build.sh" k "$accurate" >/dev/null
|
||||
D4R_PREFER_ACCURACY=1 D4R_ROCM_DIR="$ROCM" D4R_GPU_ARCH="$arch" D4R_NATIVE_FP8="$fp8" "$ROOT/kernels/build.sh" m "$accurate" >/dev/null
|
||||
if [[ "$VARIANT" == full ]]; then
|
||||
accurate_tex="$D4R_BUNDLE_TEX/accuracy/$folder"
|
||||
if [[ -f "$accurate_tex/d4r-accuracy.txt" && "$(cat "$accurate_tex/d4r-accuracy.txt")" == 1 ]]; then
|
||||
for f in "$accurate_tex"/*.hsaco; do
|
||||
[[ -f "$f" ]] || continue
|
||||
[[ -e "$accurate/$(basename "$f")" ]] || cp "$f" "$accurate/"
|
||||
done
|
||||
else
|
||||
: "${D4R_ZLUDA_EMIT:?set D4R_ZLUDA_EMIT or supply D4R_BUNDLE_TEX/accuracy/$folder}"
|
||||
D4R_PREFER_ACCURACY=1 D4R_ROCM_DIR="$ROCM" D4R_GPU_ARCH="$arch" D4R_NATIVE_FP8="$fp8" \
|
||||
D4R_DLSS_DLL="$D4R_BUNDLE_DLSS" "$ROOT/kernels/build.sh" tex "$accurate" >/dev/null
|
||||
fi
|
||||
fi
|
||||
if [[ "$VARIANT" == full ]]; then
|
||||
for f in "$STAGE/d4r/kernels/$folder"/*.hsaco; do
|
||||
[[ -f "$accurate/$(basename "$f")" ]] || {
|
||||
echo "missing accuracy variant of $(basename "$f") for $folder" >&2; exit 2;
|
||||
}
|
||||
done
|
||||
fi
|
||||
rm -f "$accurate"/*.resolution.txt
|
||||
python3 "$ROOT/kernels/tools/kernel_manifest.py" "$accurate" "${DLLS[@]}"
|
||||
}
|
||||
kernel_jobs="${D4R_PACKAGE_KERNEL_JOBS:-1}"
|
||||
[[ "$kernel_jobs" =~ ^[1-9][0-9]*$ ]] || { echo "D4R_PACKAGE_KERNEL_JOBS must be positive" >&2; exit 2; }
|
||||
pending=()
|
||||
kernel_failed=0
|
||||
for folder in "${folders[@]}"; do
|
||||
build_target "$folder" &
|
||||
pending+=("$!")
|
||||
if (( ${#pending[@]} >= kernel_jobs )); then
|
||||
wait "${pending[0]}" || kernel_failed=1
|
||||
pending=("${pending[@]:1}")
|
||||
fi
|
||||
done
|
||||
for pid in "${pending[@]}"; do wait "$pid" || kernel_failed=1; done
|
||||
[[ "$kernel_failed" == 0 ]] || { echo "native target build failed; no release ZIP created" >&2; exit 1; }
|
||||
|
||||
# licenses and sources
|
||||
ZLUDA_SRC="${D4R_ZLUDA_SRC:-$(dirname "$ZLUDA")/d4r-zluda-upstream}"
|
||||
@@ -165,6 +216,9 @@ file_version() { [[ -f "$1" ]] && strings -el "$1" | grep -A1 '^FileVersion$' |
|
||||
sed -e "s/@VERSION@/$VERSION/g" -e "s/@ZLUDA_COMMIT@/$ZLUDA_COMMIT/g" -e "s/@VKD3D_COMMIT@/$VKD3D_COMMIT/g" \
|
||||
-e "s/@DLSS_VERSION@/$(file_version "$STAGE/d4r/nvngx_dlss.dll")/g" -e "s/@NGX_VERSION@/$(file_version "$STAGE/d4r/ngx/_nvngx.dll")/g" \
|
||||
"$ROOT/packaging/SOURCES.txt" | variant > "$STAGE/d4r/source/SOURCES.txt"
|
||||
if [[ -n "${D4R_BUILD_INFO:-}" ]]; then
|
||||
cp "$D4R_BUILD_INFO" "$STAGE/d4r/source/BUILD_INFO.txt"
|
||||
fi
|
||||
sed -e "s/@VERSION@/$VERSION/g" "$ROOT/packaging/D4R_README.txt" | variant | sed 's/$/\r/' > "$STAGE/D4R_README.txt"
|
||||
|
||||
# One timestamp for every file (SOURCE_DATE_EPOCH, default the last commit): ZLUDA's kernel cache is keyed on
|
||||
|
||||
@@ -0,0 +1,165 @@
|
||||
"""CPU checks for accuracy policy, config precedence and native-set selection.
|
||||
|
||||
Run: python3 -m unittest discover -s tests -v
|
||||
Kernel arithmetic additionally needs kernel/model replays and an RTX reference.
|
||||
"""
|
||||
import os
|
||||
from pathlib import Path
|
||||
import subprocess
|
||||
import tempfile
|
||||
import unittest
|
||||
|
||||
ROOT = Path(__file__).resolve().parents[1]
|
||||
POLICY = ("D4R_ZLUDA_IGNORE_DENORMAL", "D4R_ZLUDA_WMMA_F32ACC", "D4R_ZLUDA_FAST_MATH",
|
||||
"D4R_ZLUDA_WAVE64", "D4R_ELIDE_NGX_SYNC")
|
||||
|
||||
|
||||
class AccuracyTests(unittest.TestCase):
|
||||
@classmethod
|
||||
def setUpClass(cls):
|
||||
cls.build = tempfile.TemporaryDirectory()
|
||||
cls.runner = Path(cls.build.name) / "selection"
|
||||
source = r'''
|
||||
#include "d4r_native_selection.h"
|
||||
int main(int argc, char** argv) {
|
||||
if (argc == 2 && strcmp(argv[1], "policy") == 0) {
|
||||
printf("%d", d4r_apply_accuracy_policy());
|
||||
const char* keys[] = {"D4R_ZLUDA_IGNORE_DENORMAL", "D4R_ZLUDA_WMMA_F32ACC",
|
||||
"D4R_ZLUDA_FAST_MATH", "D4R_ZLUDA_WAVE64", "D4R_ELIDE_NGX_SYNC"};
|
||||
for (unsigned i = 0; i < sizeof(keys) / sizeof(keys[0]); ++i)
|
||||
printf(" %s", getenv(keys[i]) ? getenv(keys[i]) : "unset");
|
||||
puts("");
|
||||
return 0;
|
||||
}
|
||||
if (argc != 5) return 2;
|
||||
char path[1024] = {0};
|
||||
int kind = d4r_select_native_source(argv[1], argv[2], atoi(argv[3]), atoi(argv[4]), path, sizeof(path));
|
||||
printf("%d %s\n", kind, path);
|
||||
return 0;
|
||||
}
|
||||
'''
|
||||
subprocess.run(["cc", "-x", "c", "-std=gnu11", "-Wall", "-Wextra", "-Werror",
|
||||
"-I", str(ROOT / "tools"), "-o", str(cls.runner), "-"],
|
||||
input=source, text=True, check=True, capture_output=True)
|
||||
|
||||
@classmethod
|
||||
def tearDownClass(cls):
|
||||
cls.build.cleanup()
|
||||
|
||||
def setUp(self):
|
||||
self.temp = tempfile.TemporaryDirectory()
|
||||
self.addCleanup(self.temp.cleanup)
|
||||
self.root = Path(self.temp.name)
|
||||
|
||||
def native(self, directory, accuracy=False, manifest=True):
|
||||
directory.mkdir(parents=True, exist_ok=True)
|
||||
(directory / "kernel.hsaco").write_bytes(b"fixture")
|
||||
if manifest:
|
||||
(directory / "d4r-kernels.txt").write_text("kernel 1234\n")
|
||||
if accuracy:
|
||||
(directory / "d4r-accuracy.txt").write_text("1\n")
|
||||
|
||||
def select(self, architecture="gfx1101", accuracy=True, fp8=True, directory=None):
|
||||
output = subprocess.check_output([str(self.runner), str(directory or self.root), architecture,
|
||||
str(int(accuracy)), str(int(fp8))], text=True).strip()
|
||||
kind, _, path = output.partition(" ")
|
||||
return int(kind), Path(path)
|
||||
|
||||
def test_select_accuracy_for_every_release_target(self):
|
||||
for arch in ("gfx1100", "gfx1101", "gfx1102", "gfx1103", "gfx1200", "gfx1201"):
|
||||
self.native(self.root / arch)
|
||||
accurate = self.root / "accuracy" / arch
|
||||
self.native(accurate, accuracy=True)
|
||||
self.assertEqual(self.select(arch), (1, accurate))
|
||||
self.assertEqual(self.select(arch, accuracy=False), (1, self.root / arch))
|
||||
|
||||
def test_rdna4_fp8_selection_and_widened_fallback(self):
|
||||
for arch in ("gfx1200", "gfx1201"):
|
||||
accurate = self.root / "accuracy" / arch
|
||||
fp8 = self.root / "accuracy" / (arch + "-fp8")
|
||||
self.native(accurate, accuracy=True)
|
||||
self.assertEqual(self.select(arch), (1, accurate))
|
||||
self.native(fp8, accuracy=True)
|
||||
self.assertEqual(self.select(arch), (1, fp8))
|
||||
self.assertEqual(self.select(arch, fp8=False), (1, accurate))
|
||||
|
||||
def test_missing_accuracy_never_selects_fast_or_wrong_gpu(self):
|
||||
self.native(self.root / "gfx1101")
|
||||
self.native(self.root / "accuracy" / "gfx1201", accuracy=True)
|
||||
self.assertEqual(self.select()[0], 0)
|
||||
self.native(self.root / "accuracy" / "gfx1101") # unmarked binaries
|
||||
self.assertEqual(self.select()[0], 0)
|
||||
|
||||
def test_flat_accuracy_developer_set_requires_valid_marker(self):
|
||||
self.native(self.root, manifest=False)
|
||||
self.assertEqual(self.select()[0], 0)
|
||||
self.assertEqual(self.select(accuracy=False), (2, self.root))
|
||||
(self.root / "d4r-accuracy.txt").write_text("1\n")
|
||||
self.assertEqual(self.select(), (2, self.root))
|
||||
(self.root / "d4r-accuracy.txt").write_text("0\n")
|
||||
self.assertEqual(self.select()[0], 0)
|
||||
|
||||
def test_missing_fast_target_does_not_select_release_root(self):
|
||||
self.native(self.root / "gfx1201")
|
||||
self.assertEqual(self.select(accuracy=False)[0], 0)
|
||||
|
||||
def test_accuracy_policy_overrides_conflicting_fast_settings(self):
|
||||
env = dict(os.environ, D4R_PREFER_ACCURACY="1", **dict.fromkeys(POLICY, "1"))
|
||||
output = subprocess.check_output([str(self.runner), "policy"], env=env, text=True).strip()
|
||||
self.assertEqual(output, "1 0 0 0 0 0")
|
||||
|
||||
def test_default_off_preserves_existing_policy(self):
|
||||
env = {k: v for k, v in os.environ.items() if k != "D4R_PREFER_ACCURACY"}
|
||||
env.update(dict.fromkeys(POLICY, "1"))
|
||||
output = subprocess.check_output([str(self.runner), "policy"], env=env, text=True).strip()
|
||||
self.assertEqual(output, "0 1 1 1 1 1")
|
||||
|
||||
def config(self, text, extra_env=None, expected=0):
|
||||
path = self.root / "d4r.ini"
|
||||
path.write_text(text)
|
||||
env = {k: v for k, v in os.environ.items() if not k.startswith("D4R_")}
|
||||
env.update(extra_env or {})
|
||||
result = subprocess.run(["python3", str(ROOT / "scripts/d4r_config.py"), "--config", str(path)],
|
||||
env=env, text=True, capture_output=True)
|
||||
self.assertEqual(result.returncode, expected, result.stderr)
|
||||
return result
|
||||
|
||||
def test_config_default_and_boolean_spellings(self):
|
||||
self.assertIn("export D4R_PREFER_ACCURACY=0", self.config("").stdout)
|
||||
for value in ("true", "on", "yes", "1"):
|
||||
result = self.config(f"[Kernels]\nPreferAccuracy = {value}\nNativeKernels = off\n")
|
||||
self.assertIn("export D4R_PREFER_ACCURACY=1", result.stdout)
|
||||
self.assertNotIn("D4R_ZLUDA_NATIVE_DIR", result.stdout)
|
||||
for value in ("false", "off", "no", "0"):
|
||||
self.assertIn("export D4R_PREFER_ACCURACY=0",
|
||||
self.config(f"[Kernels]\nPreferAccuracy = {value}\n").stdout)
|
||||
|
||||
def test_explicit_environment_wins_and_invalid_setting_is_reported(self):
|
||||
self.assertNotIn("export D4R_PREFER_ACCURACY",
|
||||
self.config("[Kernels]\nPreferAccuracy=true\n", {"D4R_PREFER_ACCURACY": "0"}).stdout)
|
||||
result = self.config("[Kernels]\nPreferAccuracy=perhaps\n", expected=2)
|
||||
self.assertIn("PreferAccuracy must be true or false", result.stderr)
|
||||
|
||||
def test_shipped_configs_default_off(self):
|
||||
for file in ("config/d4r.ini.default", "packaging/d4r.ini"):
|
||||
self.assertRegex((ROOT / file).read_text(), r"(?m)^PreferAccuracy\s*=\s*false$")
|
||||
|
||||
def test_builder_refuses_to_certify_mixed_fast_binaries(self):
|
||||
compiler = self.root / "rocm/lib/llvm/bin/clang++"
|
||||
compiler.parent.mkdir(parents=True)
|
||||
compiler.write_text("#!/bin/sh\nexit 99\n")
|
||||
compiler.chmod(0o755)
|
||||
output = self.root / "mixed"
|
||||
self.native(output, manifest=False)
|
||||
env = dict(os.environ, D4R_PREFER_ACCURACY="1", D4R_ROCM_DIR=str(self.root / "rocm"))
|
||||
for marker in (None, "0\n"):
|
||||
if marker is not None:
|
||||
(output / "d4r-accuracy.txt").write_text(marker)
|
||||
result = subprocess.run(["bash", str(ROOT / "kernels/build.sh"), "k", str(output)],
|
||||
env=env, text=True, capture_output=True)
|
||||
self.assertEqual(result.returncode, 2)
|
||||
self.assertIn("accuracy kernels need an empty output directory", result.stderr)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
unittest.main()
|
||||
@@ -0,0 +1,91 @@
|
||||
/* Native directory selection shared with the CPU-only configuration tests. */
|
||||
#pragma once
|
||||
#include <dirent.h>
|
||||
#include <stdio.h>
|
||||
#include <stdlib.h>
|
||||
#include <string.h>
|
||||
|
||||
static int d4r_apply_accuracy_policy(void)
|
||||
{
|
||||
const char* prefer = getenv("D4R_PREFER_ACCURACY");
|
||||
if (prefer == NULL || strcmp(prefer, "1") != 0)
|
||||
return 0;
|
||||
setenv("D4R_ZLUDA_IGNORE_DENORMAL", "0", 1);
|
||||
setenv("D4R_ZLUDA_WMMA_F32ACC", "0", 1);
|
||||
setenv("D4R_ZLUDA_FAST_MATH", "0", 1);
|
||||
setenv("D4R_ZLUDA_WAVE64", "0", 1);
|
||||
setenv("D4R_ELIDE_NGX_SYNC", "0", 1);
|
||||
return 1;
|
||||
}
|
||||
|
||||
static int d4r_accuracy_directory(const char* directory)
|
||||
{
|
||||
char path[1200], version[16];
|
||||
if (snprintf(path, sizeof(path), "%s/d4r-accuracy.txt", directory) >= (int)sizeof(path))
|
||||
return 0;
|
||||
FILE* file = fopen(path, "r");
|
||||
if (file == NULL)
|
||||
return 0;
|
||||
const int valid = fgets(version, sizeof(version), file) != NULL && strcmp(version, "1\n") == 0;
|
||||
fclose(file);
|
||||
return valid;
|
||||
}
|
||||
|
||||
/* 1 = hash-checked set, 2 = unmanifested developer set, 0 = no usable set.
|
||||
Accuracy mode never selects an unmarked directory, including flat legacy developer builds. */
|
||||
static int d4r_native_candidate(const char* directory, int accuracy)
|
||||
{
|
||||
if (accuracy && !d4r_accuracy_directory(directory))
|
||||
return 0;
|
||||
char path[1200];
|
||||
if (snprintf(path, sizeof(path), "%s/d4r-kernels.txt", directory) >= (int)sizeof(path))
|
||||
return 0;
|
||||
FILE* file = fopen(path, "r");
|
||||
if (file != NULL)
|
||||
{
|
||||
fclose(file);
|
||||
return 1;
|
||||
}
|
||||
return accuracy ? 2 : 0;
|
||||
}
|
||||
|
||||
static int d4r_select_native_source(const char* configured, const char* architecture, int accuracy,
|
||||
int fp8, char* source, size_t size)
|
||||
{
|
||||
char base[1024];
|
||||
const int length = accuracy && !d4r_accuracy_directory(configured)
|
||||
? snprintf(base, sizeof(base), "%s/accuracy", configured)
|
||||
: snprintf(base, sizeof(base), "%s", configured);
|
||||
if (length < 0 || length >= (int)sizeof(base))
|
||||
return 0;
|
||||
int kind;
|
||||
if (fp8 && strncmp(architecture, "gfx12", 5) == 0)
|
||||
{
|
||||
if (snprintf(source, size, "%s/%s-fp8", base, architecture) >= (int)size)
|
||||
return 0;
|
||||
if ((kind = d4r_native_candidate(source, accuracy)) != 0)
|
||||
return kind;
|
||||
}
|
||||
if (architecture[0] != '\0')
|
||||
{
|
||||
if (snprintf(source, size, "%s/%s", base, architecture) >= (int)size)
|
||||
return 0;
|
||||
if ((kind = d4r_native_candidate(source, accuracy)) != 0)
|
||||
return kind;
|
||||
}
|
||||
if (snprintf(source, size, "%s", base) >= (int)size)
|
||||
return 0;
|
||||
if ((kind = d4r_native_candidate(source, accuracy)) != 0)
|
||||
return kind;
|
||||
if (accuracy)
|
||||
return 0;
|
||||
/* Keep legacy flat developer directories working, but do not hand a release root to ZLUDA. */
|
||||
DIR* directory = opendir(base);
|
||||
if (directory == NULL)
|
||||
return 0;
|
||||
int targets = 0;
|
||||
for (struct dirent* entry; (entry = readdir(directory)) != NULL;)
|
||||
targets += strncmp(entry->d_name, "gfx", 3) == 0;
|
||||
closedir(directory);
|
||||
return targets ? 0 : 2;
|
||||
}
|
||||
+102
-13
@@ -221,6 +221,7 @@ struct CudaApi
|
||||
int(WINAPI* ctxSynchronize)() = nullptr;
|
||||
int(WINAPI* eventCreate)(CudaEvent*, unsigned int) = nullptr;
|
||||
int(WINAPI* eventRecord)(CudaEvent, void*) = nullptr;
|
||||
int(WINAPI* eventSynchronize)(CudaEvent) = nullptr;
|
||||
int(WINAPI* eventElapsedTime)(float*, CudaEvent, CudaEvent) = nullptr;
|
||||
int(WINAPI* eventDestroy)(CudaEvent) = nullptr;
|
||||
// Optional: overlapped staging (see async_copies()).
|
||||
@@ -528,6 +529,8 @@ static void load_portable_config()
|
||||
|
||||
// Native kernels: d4r\kernels, each used only when DLSS's PTX for it matches (see the bridge).
|
||||
const std::string native = ascii_lower(ini_value(ini, "kernels", "NativeKernels"));
|
||||
// The bridge selects accuracy variants and enforces their compiler/sync policy before cuInit.
|
||||
portable_set_unix("D4R_PREFER_ACCURACY", ini_flag(ini, "kernels", "PreferAccuracy", 0) ? "1" : "0");
|
||||
const bool nativeOn = native.empty() || native == "on" || native == "true" || native == "1" || native == "fast";
|
||||
if (!nativeOn && native != "off" && native != "false" && native != "0")
|
||||
g_portable.notes.push_back("d4r.ini: [Kernels] NativeKernels must be on or off, not '" + native + "'");
|
||||
@@ -656,6 +659,16 @@ static double profile_ms(ProfileClock::time_point start, ProfileClock::time_poin
|
||||
return std::chrono::duration<double, std::milli>(end - start).count();
|
||||
}
|
||||
|
||||
static double profile_thread_cpu_ms()
|
||||
{
|
||||
FILETIME created = {}, exited = {}, kernel = {}, user = {};
|
||||
if (!GetThreadTimes(GetCurrentThread(), &created, &exited, &kernel, &user))
|
||||
return -1.0;
|
||||
const uint64_t kernelTicks = (static_cast<uint64_t>(kernel.dwHighDateTime) << 32) | kernel.dwLowDateTime;
|
||||
const uint64_t userTicks = (static_cast<uint64_t>(user.dwHighDateTime) << 32) | user.dwLowDateTime;
|
||||
return static_cast<double>(kernelTicks + userTicks) / 10000.0;
|
||||
}
|
||||
|
||||
// --- CUDA worker thread --------------------------------------------------------
|
||||
// Every NGX-core and CUDA call runs on this thread so the ZLUDA context that
|
||||
// the nvcuda bridge creates on first use stays current.
|
||||
@@ -1292,14 +1305,18 @@ static bool load_libraries()
|
||||
g.cu.outputKernelNative = nullptr;
|
||||
if (!load_export(g.cuda, "d4rRegisterLinearTexture", g.cu.registerLinearTexture))
|
||||
g.cu.registerLinearTexture = nullptr;
|
||||
if (profile_enabled())
|
||||
if (profile_enabled() || env_uint("D4R_SHIM_BLOCKING_SYNC", 0) != 0)
|
||||
{
|
||||
const bool events = load_export(g.cuda, "cuEventCreate", g.cu.eventCreate) &&
|
||||
load_export(g.cuda, "cuEventRecord", g.cu.eventRecord) &&
|
||||
load_export(g.cuda, "cuEventElapsedTime", g.cu.eventElapsedTime) &&
|
||||
load_export(g.cuda, "cuEventDestroy", g.cu.eventDestroy);
|
||||
if (!events)
|
||||
const bool create = load_export(g.cuda, "cuEventCreate", g.cu.eventCreate);
|
||||
const bool record = load_export(g.cuda, "cuEventRecord", g.cu.eventRecord);
|
||||
const bool wait = env_uint("D4R_SHIM_BLOCKING_SYNC", 0) != 0
|
||||
? load_export(g.cuda, "d4rEventSynchronize", g.cu.eventSynchronize) : true;
|
||||
const bool destroy = load_export(g.cuda, "cuEventDestroy", g.cu.eventDestroy);
|
||||
const bool elapsed = profile_enabled() ? load_export(g.cuda, "cuEventElapsedTime", g.cu.eventElapsedTime) : true;
|
||||
if (profile_enabled() && !(create && record && destroy && elapsed))
|
||||
logf("D4R_PROFILE: CUDA event timing unavailable; CPU stage timings remain enabled");
|
||||
if (env_uint("D4R_SHIM_BLOCKING_SYNC", 0) != 0 && !(create && record && wait && destroy))
|
||||
logf("blocking output wait unavailable; using context sync");
|
||||
}
|
||||
logf("loaded NGX core %ls and nvcuda.dll: %s", corePath, ok ? "all exports present" : "exports missing");
|
||||
return ok;
|
||||
@@ -1484,6 +1501,9 @@ struct FrameTiming
|
||||
double download = 0, outputConvert = 0;
|
||||
double prep = 0, worker = 0, workerWait = 0, finishWait = 0, markerWait = 0;
|
||||
double ngxHost = 0, ctxSync = 0, gpuEval = -1;
|
||||
bool gpuEventsRecorded = false;
|
||||
double outputSyncWall = 0, outputSyncCpu = -1;
|
||||
bool outputSyncBlocking = false;
|
||||
double h2dTotal = 0, d2hIssue = 0, d2hWait = 0;
|
||||
ProfileClock::time_point prepStart, workerQueued, finishQueued;
|
||||
size_t queueDepth = 0;
|
||||
@@ -1536,6 +1556,7 @@ struct Feature
|
||||
int quality = 0, flags = 0;
|
||||
unsigned int preset = 0;
|
||||
CudaEvent profileStart = nullptr, profileEnd = nullptr;
|
||||
CudaEvent outputReadyEvent = nullptr;
|
||||
bool profileEventsReady = false;
|
||||
|
||||
CudaImage color, depth, motion, exposure, output;
|
||||
@@ -1590,6 +1611,7 @@ struct Feature
|
||||
ID3D12Resource* marker = nullptr;
|
||||
volatile uint32_t* markerValue = nullptr;
|
||||
uint32_t frame = 0;
|
||||
uint32_t rejectedFormatCount = 0; // game thread; rate-limits format diagnostics
|
||||
std::atomic<int> latestOutput{-1};
|
||||
std::atomic<uint32_t> completedFrames{0};
|
||||
uint32_t evaluatedFrames = 0; // worker only
|
||||
@@ -3613,7 +3635,40 @@ static void publish_vram(Feature* feature, uint32_t frame, const FrameParams& pa
|
||||
copy.Height = feature->output.height;
|
||||
int result = rowBytes * feature->output.height > buffer.bytes ? -1 : feature->outputRedirected ? 0 : copy_2d(copy);
|
||||
if (result == 0)
|
||||
{
|
||||
const auto syncStart = timing.enabled ? ProfileClock::now() : ProfileClock::time_point{};
|
||||
const double cpuStart = timing.enabled ? profile_thread_cpu_ms() : -1.0;
|
||||
if (feature->outputReadyEvent != nullptr)
|
||||
{
|
||||
const int recordResult = g.cu.eventRecord(feature->outputReadyEvent, nullptr);
|
||||
const int waitResult = recordResult == 0 ? g.cu.eventSynchronize(feature->outputReadyEvent) : recordResult;
|
||||
if (waitResult == 0)
|
||||
timing.outputSyncBlocking = true;
|
||||
else
|
||||
{
|
||||
logf("frame %u: blocking output wait failed (record %d, wait %d); using context sync", frame,
|
||||
recordResult, waitResult);
|
||||
result = g.cu.ctxSynchronize();
|
||||
g.cu.eventDestroy(feature->outputReadyEvent);
|
||||
feature->outputReadyEvent = nullptr;
|
||||
}
|
||||
}
|
||||
else
|
||||
result = g.cu.ctxSynchronize();
|
||||
if (timing.enabled)
|
||||
{
|
||||
timing.outputSyncWall = profile_ms(syncStart, ProfileClock::now());
|
||||
const double cpuEnd = profile_thread_cpu_ms();
|
||||
if (cpuStart >= 0.0 && cpuEnd >= 0.0)
|
||||
timing.outputSyncCpu = std::max(0.0, cpuEnd - cpuStart);
|
||||
}
|
||||
}
|
||||
if (result == 0 && timing.gpuEventsRecorded)
|
||||
{
|
||||
float gpuEvalMs = -1.0f;
|
||||
if (g.cu.eventElapsedTime(&gpuEvalMs, feature->profileStart, feature->profileEnd) == 0)
|
||||
timing.gpuEval = gpuEvalMs;
|
||||
}
|
||||
if (result != 0)
|
||||
{
|
||||
logf("frame %u: VRAM output copy failed: %d", frame, result);
|
||||
@@ -3802,8 +3857,9 @@ static void run_evaluation(Feature* feature, int slotIndex, uint32_t frame, Fram
|
||||
static const bool evalSync = env_uint("D4R_SHIM_EVAL_SYNC", 1) != 0;
|
||||
const int syncResult = params.vram && !evalSync ? 0 : g.cu.ctxSynchronize();
|
||||
const auto evaluated = ProfileClock::now();
|
||||
const bool gpuEventsRecorded = eventStartResult == 0 && eventEndResult == 0;
|
||||
float gpuEvalMs = -1.0f;
|
||||
if (eventStartResult == 0 && eventEndResult == 0 && syncResult == 0 &&
|
||||
if (gpuEventsRecorded && syncResult == 0 && (!params.vram || evalSync) &&
|
||||
g.cu.eventElapsedTime(&gpuEvalMs, feature->profileStart, feature->profileEnd) != 0)
|
||||
gpuEvalMs = -1.0f;
|
||||
if (params.vram && !gpuWait)
|
||||
@@ -3825,6 +3881,7 @@ static void run_evaluation(Feature* feature, int slotIndex, uint32_t frame, Fram
|
||||
timing.ngxHost = profile_ms(evalStart, evalReturned);
|
||||
timing.ctxSync = profile_ms(syncStart, evaluated);
|
||||
timing.gpuEval = gpuEvalMs;
|
||||
timing.gpuEventsRecorded = gpuEventsRecorded && params.vram && !evalSync;
|
||||
}
|
||||
if (params.vram)
|
||||
{
|
||||
@@ -3988,7 +4045,8 @@ static void finish_publish(Feature* feature, int target, uint32_t frame, const F
|
||||
"d3d_input_record=%.3f d3d_output_record=%.3f game_call=%.3f "
|
||||
"color_convert=%.3f depth_convert=%.3f motion_convert=%.3f exposure_convert=%.3f "
|
||||
"color_h2d=%.3f depth_h2d=%.3f motion_h2d=%.3f exposure_h2d=%.3f "
|
||||
"ngx_host=%.3f ctx_sync=%.3f gpu_eval=%.3f d2h=%.3f output_convert=%.3f "
|
||||
"ngx_host=%.3f ctx_sync=%.3f gpu_eval=%.3f output_sync_wall=%.3f "
|
||||
"output_sync_cpu=%.3f output_sync_blocking=%d d2h=%.3f output_convert=%.3f "
|
||||
"h2d_total=%.3f d2h_issue=%.3f d2h_wait=%.3f "
|
||||
"prep=%.3f worker_wait=%.3f worker=%.3f finish_wait=%.3f finish=%.3f pipeline=%.3f "
|
||||
"throughput_interval=%.3f presented=%u age=%d",
|
||||
@@ -4001,7 +4059,8 @@ static void finish_publish(Feature* feature, int target, uint32_t frame, const F
|
||||
timing.inputRecord, timing.outputRecord, timing.gameCall,
|
||||
timing.convert[0], timing.convert[1], timing.convert[2], timing.convert[3],
|
||||
timing.upload[0], timing.upload[1], timing.upload[2], timing.upload[3],
|
||||
timing.ngxHost, timing.ctxSync, timing.gpuEval, timing.download, timing.outputConvert,
|
||||
timing.ngxHost, timing.ctxSync, timing.gpuEval, timing.outputSyncWall, timing.outputSyncCpu,
|
||||
timing.outputSyncBlocking, timing.download, timing.outputConvert,
|
||||
timing.h2dTotal, timing.d2hIssue, timing.d2hWait,
|
||||
timing.prep, timing.workerWait, timing.worker, timing.finishWait, profile_ms(start, finished),
|
||||
profile_ms(timing.prepStart, finished), interval,
|
||||
@@ -4296,6 +4355,22 @@ D4R_EXPORT NgxResult NVSDK_NGX_D3D12_CreateFeature(ID3D12GraphicsCommandList*, u
|
||||
else
|
||||
feature->scratch = 0;
|
||||
const NgxResult created = g.ngx.createFeature(NGX_FEATURE_SUPER_SAMPLING, p, &feature->cudaHandle);
|
||||
if (created == NGX_SUCCESS && env_uint("D4R_SHIM_BLOCKING_SYNC", 0) != 0 &&
|
||||
g.cu.eventCreate != nullptr && g.cu.eventRecord != nullptr &&
|
||||
g.cu.eventSynchronize != nullptr && g.cu.eventDestroy != nullptr)
|
||||
{
|
||||
// All VRAM-path input waits, NGX kernels and output copies use the null stream.
|
||||
// A blocking event yields the CPU while the GPU finishes that stream.
|
||||
constexpr unsigned int kBlockingSyncNoTiming = 0x1u | 0x2u;
|
||||
const int eventResult = g.cu.eventCreate(&feature->outputReadyEvent, kBlockingSyncNoTiming);
|
||||
if (eventResult != 0)
|
||||
{
|
||||
logf("blocking output wait unavailable (cuEventCreate %d); using context sync", eventResult);
|
||||
feature->outputReadyEvent = nullptr;
|
||||
}
|
||||
else
|
||||
logf("blocking output wait enabled for this feature");
|
||||
}
|
||||
if (created == NGX_SUCCESS && profile_enabled() && g.cu.eventCreate != nullptr &&
|
||||
g.cu.eventRecord != nullptr && g.cu.eventElapsedTime != nullptr && g.cu.eventDestroy != nullptr)
|
||||
{
|
||||
@@ -4396,11 +4471,23 @@ static NgxResult evaluate(ID3D12GraphicsCommandList* list, const NgxHandle* hand
|
||||
colorDesc.Width, colorDesc.Height, colorDesc.Format, depthDesc.Width, depthDesc.Height, depthDesc.Format,
|
||||
motionDesc.Width, motionDesc.Height, motionDesc.Format, outputDesc.Width, outputDesc.Height,
|
||||
outputDesc.Format, exposure);
|
||||
if (!supported_input(Plane::Color, colorDesc.Format) || !supported_input(Plane::Depth, depthDesc.Format) ||
|
||||
!supported_input(Plane::Motion, motionDesc.Format) || !supported_output(outputDesc.Format))
|
||||
const bool colorSupported = supported_input(Plane::Color, colorDesc.Format);
|
||||
const bool depthSupported = supported_input(Plane::Depth, depthDesc.Format);
|
||||
const bool motionSupported = supported_input(Plane::Motion, motionDesc.Format);
|
||||
const bool outputSupported = supported_output(outputDesc.Format);
|
||||
if (!colorSupported || !depthSupported || !motionSupported || !outputSupported)
|
||||
{
|
||||
if (frame <= 3)
|
||||
logf("evaluate frame %u: unsupported format", frame);
|
||||
// Log the first failures even if they occur well after startup, then periodically.
|
||||
const uint32_t rejected = ++feature->rejectedFormatCount;
|
||||
if (rejected <= 3 || rejected % 120 == 0)
|
||||
logf("evaluate feature %u frame %u: unsupported format (rejection %u): "
|
||||
"color %llux%u fmt=%d%s, depth %llux%u fmt=%d%s, "
|
||||
"mv %llux%u fmt=%d%s, output %llux%u fmt=%d%s",
|
||||
feature->handle.Id, frame, rejected,
|
||||
colorDesc.Width, colorDesc.Height, colorDesc.Format, colorSupported ? "" : " (unsupported)",
|
||||
depthDesc.Width, depthDesc.Height, depthDesc.Format, depthSupported ? "" : " (unsupported)",
|
||||
motionDesc.Width, motionDesc.Height, motionDesc.Format, motionSupported ? "" : " (unsupported)",
|
||||
outputDesc.Width, outputDesc.Height, outputDesc.Format, outputSupported ? "" : " (unsupported)");
|
||||
return NGX_FAIL_UNSUPPORTED_FORMAT;
|
||||
}
|
||||
if (exposure != nullptr)
|
||||
@@ -4710,6 +4797,8 @@ static void release_feature(Feature* feature)
|
||||
g.cu.eventDestroy(feature->profileStart);
|
||||
if (feature->profileEnd != nullptr)
|
||||
g.cu.eventDestroy(feature->profileEnd);
|
||||
if (feature->outputReadyEvent != nullptr)
|
||||
g.cu.eventDestroy(feature->outputReadyEvent);
|
||||
if (feature->scratch != 0)
|
||||
g.cu.memFree(feature->scratch);
|
||||
for (CudaDevicePtr buffer : feature->planeLinear)
|
||||
|
||||
+72
-30
@@ -11,6 +11,7 @@
|
||||
#include <string.h>
|
||||
#include <sys/stat.h>
|
||||
#include <unistd.h>
|
||||
#include "d4r_native_selection.h"
|
||||
|
||||
typedef int CUresult;
|
||||
typedef int CUdevice;
|
||||
@@ -443,39 +444,28 @@ static void prepare_native_kernels(const char* cache_home)
|
||||
/* RDNA4 with native FP8 WMMA (D4R_ZLUDA_WMMA_FP8_NATIVE=1, d4r.ini NativeFp8): the <target>-fp8 variant,
|
||||
whose kernels match ZLUDA's FP8 lowering; no other GPU has such a directory */
|
||||
const char* fp8 = getenv("D4R_ZLUDA_WMMA_FP8_NATIVE");
|
||||
if (fp8 != NULL && strcmp(fp8, "1") == 0 && strncmp(architecture, "gfx12", 5) == 0)
|
||||
const char* prefer = getenv("D4R_PREFER_ACCURACY");
|
||||
const int accuracy = prefer != NULL && strcmp(prefer, "1") == 0;
|
||||
const int kind = d4r_select_native_source(configured, architecture, accuracy,
|
||||
fp8 != NULL && strcmp(fp8, "1") == 0, source, sizeof(source));
|
||||
if (kind == 0)
|
||||
{
|
||||
snprintf(source, sizeof(source), "%s/%s-fp8", configured, architecture);
|
||||
snprintf(path, sizeof(path), "%s/d4r-kernels.txt", source);
|
||||
manifest = fopen(path, "r");
|
||||
}
|
||||
if (manifest == NULL)
|
||||
{
|
||||
snprintf(source, sizeof(source), "%s/%s", configured, architecture);
|
||||
snprintf(path, sizeof(path), "%s/d4r-kernels.txt", source);
|
||||
manifest = architecture[0] != '\0' ? fopen(path, "r") : NULL;
|
||||
}
|
||||
if (manifest == NULL)
|
||||
{
|
||||
snprintf(source, sizeof(source), "%s", configured);
|
||||
snprintf(path, sizeof(path), "%s/d4r-kernels.txt", source);
|
||||
manifest = fopen(path, "r");
|
||||
}
|
||||
if (manifest == NULL)
|
||||
{
|
||||
/* a developer directory is used as it is; a release one without this GPU's target is not */
|
||||
DIR* directory = opendir(configured);
|
||||
int targets = 0;
|
||||
for (struct dirent* entry; directory != NULL && (entry = readdir(directory)) != NULL;)
|
||||
targets += strncmp(entry->d_name, "gfx", 3) == 0;
|
||||
if (directory != NULL)
|
||||
closedir(directory);
|
||||
if (targets != 0)
|
||||
{
|
||||
tracef("native kernels: none for this GPU (%s) in %s; ZLUDA compiles every DLSS kernel",
|
||||
architecture[0] != '\0' ? architecture : "unknown target", configured);
|
||||
tracef("native kernels: no %sset for this GPU (%s) in %s; ZLUDA compiles every DLSS kernel",
|
||||
accuracy ? "accuracy " : "", architecture[0] != '\0' ? architecture : "unknown target", configured);
|
||||
unsetenv("D4R_ZLUDA_NATIVE_DIR");
|
||||
return;
|
||||
}
|
||||
if (kind == 2)
|
||||
{
|
||||
setenv("D4R_ZLUDA_NATIVE_DIR", source, 1);
|
||||
tracef("native kernels: %sdeveloper set in %s", accuracy ? "accuracy " : "", source);
|
||||
return;
|
||||
}
|
||||
snprintf(path, sizeof(path), "%s/d4r-kernels.txt", source);
|
||||
manifest = fopen(path, "r");
|
||||
if (manifest == NULL)
|
||||
{
|
||||
unsetenv("D4R_ZLUDA_NATIVE_DIR");
|
||||
return;
|
||||
}
|
||||
char line[512];
|
||||
@@ -767,6 +757,13 @@ int WINAPI d4rOutputKernelNative(void)
|
||||
|
||||
static void load_zluda(void)
|
||||
{
|
||||
/* A policy switch, applied before ZLUDA loads or reads its compilation/cache settings. This
|
||||
also covers native-off and missing/version-mismatched native kernels. */
|
||||
const int accuracy = d4r_apply_accuracy_policy();
|
||||
if (accuracy)
|
||||
{
|
||||
tracef("PreferAccuracy on: original denormal handling, per-MMA rounding, wave32 and NGX synchronizations");
|
||||
}
|
||||
/* D4R_ZLUDA_LIBCUDA may name ZLUDA's libcuda.so directly, for processes
|
||||
(such as Proton games) whose library search path is not ours. */
|
||||
const char* configured = getenv("D4R_ZLUDA_LIBCUDA");
|
||||
@@ -796,6 +793,28 @@ static void load_zluda(void)
|
||||
expand_home(cache, cache_home, sizeof(cache_home));
|
||||
make_directories(cache_home);
|
||||
}
|
||||
if (accuracy)
|
||||
{
|
||||
/* FAST_MATH is not fingerprinted by older ZLUDA runtimes. Use a separate cache even
|
||||
when a previous run explicitly enabled that experimental compiler switch. */
|
||||
char base[1024];
|
||||
const char* xdg = getenv("XDG_CACHE_HOME");
|
||||
if (cache_home[0] != '\0')
|
||||
snprintf(base, sizeof(base), "%s", cache_home);
|
||||
else if (xdg != NULL && xdg[0] != '\0')
|
||||
snprintf(base, sizeof(base), "%s", xdg);
|
||||
else
|
||||
{
|
||||
const char* home = getenv("HOME");
|
||||
snprintf(base, sizeof(base), "%s/.cache", home != NULL ? home : "/tmp");
|
||||
}
|
||||
if (snprintf(cache_home, sizeof(cache_home), "%s/d4r-accuracy", base) >= (int)sizeof(cache_home))
|
||||
{
|
||||
set_load_error("accuracy cache path is too long");
|
||||
return;
|
||||
}
|
||||
make_directories(cache_home);
|
||||
}
|
||||
prepare_native_kernels(cache_home[0] != '\0' ? cache_home : NULL);
|
||||
if (cache_home[0] != '\0')
|
||||
{
|
||||
@@ -2263,7 +2282,18 @@ CUresult WINAPI cuArrayDestroy(CUarray array)
|
||||
CUARRAYDESTROY_FN function = (CUARRAYDESTROY_FN)find_zluda_symbol("cuArrayDestroy");
|
||||
CUresult result = function != NULL ? function(array) : missing("cuArrayDestroy");
|
||||
if (result == CUDA_SUCCESS)
|
||||
{
|
||||
/* A recycled array handle must not inherit a released feature's output target. */
|
||||
pthread_mutex_lock(&instrumentation_lock);
|
||||
if (redirect_array == array)
|
||||
{
|
||||
redirect_array = NULL;
|
||||
redirect_pointer = 0;
|
||||
redirect_pitch = 0;
|
||||
}
|
||||
pthread_mutex_unlock(&instrumentation_lock);
|
||||
forget_array_descriptor(array);
|
||||
}
|
||||
TRACE_CALL(result, "cuArrayDestroy array=%p result=%d", array, result);
|
||||
return result;
|
||||
}
|
||||
@@ -2537,6 +2567,18 @@ CUresult WINAPI cuEventSynchronize(D4rArg a0)
|
||||
TRACE_CALL(result, "cuEventSynchronize->cuEventSynchronize result=%d", result);
|
||||
return result;
|
||||
}
|
||||
/* The shim's output wait must not inherit D4R_ELIDE_NGX_SYNC: it releases the
|
||||
game's split command list only after this event has actually completed. */
|
||||
CUresult WINAPI d4rEventSynchronize(D4rArg a0)
|
||||
{
|
||||
typedef CUresult(__attribute__((sysv_abi)) * function_type)(D4rArg);
|
||||
function_type function = (function_type)find_zluda_symbol("cuEventSynchronize");
|
||||
CUresult result = function != NULL ? function(a0) : missing("cuEventSynchronize");
|
||||
if (result == CUDA_SUCCESS)
|
||||
flush_kernel_profiles();
|
||||
TRACE_CALL(result, "d4rEventSynchronize result=%d", result);
|
||||
return result;
|
||||
}
|
||||
D4R_FORWARD(cuEventQuery, cuEventQuery, 1, (D4rArg a0), (a0))
|
||||
/* With elided event waits an event may still be pending: report 0 ms instead of CUDA_ERROR_NOT_READY. */
|
||||
CUresult WINAPI cuEventElapsedTime(D4rArg a0, D4rArg a1, D4rArg a2)
|
||||
|
||||
@@ -92,6 +92,7 @@
|
||||
@ stdcall d4rReleaseVulkanMemory(ptr) d4rReleaseVulkanMemory
|
||||
@ stdcall d4rMemcpy2DAsync(ptr ptr) d4rMemcpy2DAsync
|
||||
@ stdcall d4rCtxSynchronize() d4rCtxSynchronize
|
||||
@ stdcall d4rEventSynchronize(ptr) d4rEventSynchronize
|
||||
@ stdcall d4rStreamWaitValue32(int64 long) d4rStreamWaitValue32
|
||||
@ stdcall d4rWriteValue32(int64 long) d4rWriteValue32
|
||||
@ stdcall d4rSetArrayRedirect(ptr int64 long) d4rSetArrayRedirect
|
||||
|
||||
Reference in new issue
Block a user