Fix DLSS artifacts and improve synchronization diagnostics
- Fix Cyberpunk 2077 preset-K black artifacts by preserving FP16/FP64
  denormal requirements while limiting denormal suppression to FP32.

- Fix stale direct-output redirects after array destruction, preventing
  reused handles from inheriting an earlier feature's output buffer.

- Log rejected resource formats and dimensions, including failures after
  startup, with rate limiting for repeated errors.

- Add opt-in blocking output synchronization with a dedicated bridge
  export and fallback to context synchronization.

- Report output-wait CPU and wall time, and defer GPU timing queries
  until asynchronous evaluation has completed. The CPU-overhead
  mitigation for #7 still needs reporter confirmation.

- Reject release libraries requiring GLIBC newer than the configured
  baseline, defaulting to 2.41, and document compatible builds.

Validation: shim and bridge builds pass; targeted redirect-lifetime and
format-logging checks pass.

Fixes #5
Fixes #8
Refs #7
This commit is contained in:
 ayo committed
1 parent
4334a0c3c4
commit
b2b3781aca
12 files changed
+199
-24
No files matched your search
@@ -2,7 +2,7 @@
|
||||
|
||||
d4r runs NVIDIA's official DLSS Super Resolution library (`nvngx_dlss.dll`) in Windows games on AMD Radeon GPUs under Linux and Proton. The game asks for DLSS as usual; the DLSS network runs on the AMD GPU through [ZLUDA](https://github.com/vosen/ZLUDA) (CUDA on ROCm/HIP), with the heaviest DLSS kernels replaced by hand-written RDNA3 and RDNA4 code.
|
||||
|
||||
**Supported DLSS models:** DLSS 3 CNN (E), DLSS 4 transformer (K, default), and DLSS 4.5 transformer (M). DLSS 5 is not supported.
|
||||
**Supported DLSS models:** DLSS 3 CNN (E), DLSS 4 transformer (K, default), and DLSS 4.5 transformer (M). DLSS 5 is PURPOSELY not supported.
|
||||
|
||||
**Proof of concept:** d4r shows that DLSS can run on an AMD GPU, but it is not really that practical for everyday use yet. It has been tested on one GPU in a handful of games and depends on unreleased patches to ZLUDA and vkd3d-proton.
|
||||
|
||||
@@ -31,16 +31,16 @@ On the same GPU DLSS starts at a disadvantage: its networks were designed for NV
|
||||
|
||||
## Known issues
|
||||
|
||||
- In some games native upscaling can show visible artifacting.
|
||||
- In some games using some models native upscaling can show visible artifacting.
|
||||
|
||||
## GPU support
|
||||
|
||||
d4r builds for RDNA3 and RDNA4. A newly built release compiles native DLSS 4 and 4.5 network kernels for the targets below and selects the matching set at runtime. Only the RX 7700 XT has been tested on a real GPU; RDNA4 runtime and performance remain unverified on hardware.
|
||||
d4r builds for RDNA3 and RDNA4. A newly built release compiles native DLSS 4 and 4.5 network kernels for the targets below and selects the matching set at runtime. Only the RX 7700 XT has been tested by this project on a real GPU; an external video reports DLSS 4.5 running through d4r 0.1.2 on an RX 7900 XTX. RDNA4 runtime and performance remain unverified on hardware.
|
||||
|
||||
| GPU | Chip | FP8 math | Runtime testing |
|
||||
|---|---|---|---|
|
||||
| RX 7700 XT, RX 7800 XT, RX 7700, Radeon PRO W7700 | gfx1101 | widened to f16 | RX 7700 XT only |
|
||||
| RX 7900 GRE / XT / XTX, Radeon PRO W7800 / W7900 | gfx1100 | widened to f16 | untested |
|
||||
| RX 7900 GRE / XT / XTX, Radeon PRO W7800 / W7900 | gfx1100 | widened to f16 | RX 7900 XTX: [external video](https://www.youtube.com/watch?v=_GLjJ2Dn5pU) (DLSS 4.5); other cards untested |
|
||||
| RX 7600 / 7600 XT, RX 7650 GRE | gfx1102 | widened to f16 | untested |
|
||||
| RDNA3 integrated GPUs | gfx1103 | widened to f16 | untested |
|
||||
| RX 9070 XT / 9070 / 9070 GRE, Radeon AI PRO R9700 | gfx1201 | native FP8 (`NativeFp8`, default on) | emulator only |
|
||||
@@ -136,9 +136,15 @@ Gameplay recordings of each DLSS model at the Quality, Performance and Ultra Per
|
||||
| `packaging/` | the release's `d4r.ini`, OptiScaler settings, user guide and install check |
|
||||
| `docs/` | architecture, build, native kernel and performance notes |
|
||||
|
||||
## Stars
|
||||
## Star History
|
||||
|
||||
[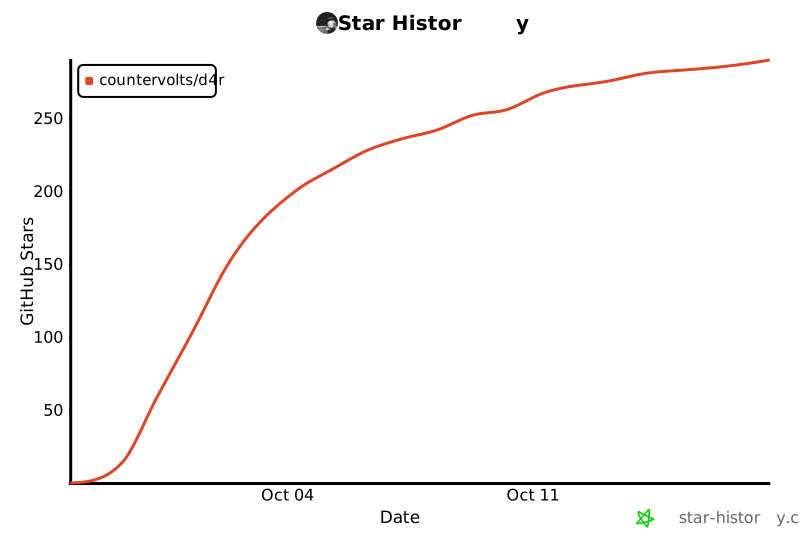](https://star-history.com/#countervolts/d4r&Date)
|
||||
<a href="https://www.star-history.com/?type=date&repos=countervolts%2Fd4r">
|
||||
<picture>
|
||||
<source media="(prefers-color-scheme: dark)" srcset="https://api.star-history.com/chart?repos=countervolts/d4r&type=date&theme=dark&legend=top-left" />
|
||||
<source media="(prefers-color-scheme: light)" srcset="https://api.star-history.com/chart?repos=countervolts/d4r&type=date&legend=top-left" />
|
||||
<img alt="Star History Chart" src="https://api.star-history.com/chart?repos=countervolts/d4r&type=date&legend=top-left" />
|
||||
</picture>
|
||||
</a>
|
||||
|
||||
## License
|
||||
|
||||
|
||||
@@ -19,6 +19,10 @@ The following DirectX 12 games run DLSS Super Resolution through d4r on the test
|
||||
| Ratchet & Clank: Rift Apart | Works; occasional artifacts in the pause menu | Works; minor artifacts with HDR enabled and occasionally in the pause menu | Works; occasional artifacts in the pause menu |
|
||||
| Dying Light: The Beast | Works | Works | Works; small visual artifacts throughout |
|
||||
|
||||
Unsupported games:
|
||||
|
||||
- **DOOM: The Dark Ages:** the game uses Vulkan and has no D3D12 mode. d4r currently supports D3D12 DLSS only, so its DLSS calls cannot reach d4r. The game's hardware ray-tracing requirement is separate from this limitation.
|
||||
|
||||
General notes:
|
||||
|
||||
- Select DLSS in the game's graphics settings where it is offered. OptiScaler can also feed DLSS from a game's FSR or XeSS inputs, but those are a fallback for games that hide DLSS and can ghost or show a black screen.
|
||||
|
||||
@@ -127,3 +127,4 @@ LogDir = auto
|
||||
[Env]
|
||||
; Anything else, passed through as environment variables (one per line):
|
||||
; D4R_SHIM_SPLIT_TIMEOUT_MS = 200
|
||||
; D4R_SHIM_BLOCKING_SYNC = 1 ; yield CPU while waiting for DLSS output
|
||||
@@ -88,3 +88,12 @@ The release zip (`scripts/package_release.sh`) is unpacked into the folder that
|
||||
## Logs
|
||||
|
||||
The launcher writes each run's logs to `~/.cache/d4r-dlss-captures/game-<exe>-<time>/`. `d4r_nvngx.log` holds the shim's log. With `[Debug] Profile = true` it also records one `D4R_PROFILE` line per frame, with the stage timings.
|
||||
|
||||
For a CPU-use A/B check, set `D4R_SHIM_BLOCKING_SYNC = 1` under `[Env]` in the game's `d4r.ini`.
|
||||
The VRAM path then requests a blocking event wait for its null-stream output. If ZLUDA and HIP
|
||||
honour the event flag, the waiting thread yields the CPU; an unavailable or failed event falls back
|
||||
to the original context sync. This is opt-in because it changes the wait scope and may add wakeup
|
||||
latency. The profile reports `output_sync_wall`, `output_sync_cpu`, and `output_sync_blocking`;
|
||||
compare CPU use and frame rate in the same scene.
|
||||
The `d2h` field on this path includes the output synchronization wait, even when direct output
|
||||
skips the array-to-buffer copy.
|
||||
@@ -27,6 +27,13 @@ cp target/release/libnvcuda.so ~/.cache/d4r-zluda-current/
|
||||
ln -sf libnvcuda.so ~/.cache/d4r-zluda-current/libcuda.so
|
||||
```
|
||||
|
||||
Build the release ZLUDA library on a system or in a container with GLIBC 2.41 or older. A binary
|
||||
linked on a newer system can require newer GLIBC symbols even when the ZLUDA source does not need new
|
||||
GLIBC features. Before packaging, check it with
|
||||
`scripts/check_glibc_compat.sh 2.41 /path/to/libnvcuda.so`. The release packager runs the same
|
||||
check on ZLUDA, the Wine CUDA bridge, and every bundled ROCm library. Test the rebuilt library
|
||||
with the D3D12 harness and in a game before publishing a release.
|
||||
|
||||
The launcher looks for ZLUDA in `D4R_ZLUDA_DIR` (default `~/.cache/d4r-zluda-current`, or `ZludaDir` in d4r.ini).
|
||||
|
||||
What the patches add:
|
||||
|
||||
@@ -55,3 +55,5 @@ Profile = false
|
||||
|
||||
[Env]
|
||||
; Extra environment variables for d4r, NAME = value.
|
||||
; Use a blocking CUDA event while waiting for DLSS output.
|
||||
; D4R_SHIM_BLOCKING_SYNC = 1
|
||||
@@ -1225,9 +1225,10 @@ index e6f22a6..4256ae5 100644
|
||||
Kernel(SpirvWord),
|
||||
}
|
||||
|
||||
+// d4r: D4R_ZLUDA_IGNORE_DENORMAL=1 drops per-instruction denormal (.ftz) requirements, so a kernel
|
||||
+// keeps one denormal mode instead of switching it around ftz instructions (differences only for
|
||||
+// values below ~1e-38). Not part of the JIT cache key: use a fresh cache when toggling it.
|
||||
+// d4r: D4R_ZLUDA_IGNORE_DENORMAL=1 drops only FP32 denormal (.ftz) requirements to avoid mode switches.
|
||||
+// Keep FP16/FP64 requirements: flushing FP16 values below 2^-14 corrupts K's output and can make its
|
||||
+// translated attention layers non-finite. The runtime fingerprints code-generation switches in the
|
||||
+// JIT cache key; native texture code objects must also be rebuilt after changing this policy.
|
||||
+fn ignore_denormal_modes() -> bool {
|
||||
+ static VALUE: std::sync::OnceLock<bool> = std::sync::OnceLock::new();
|
||||
+ *VALUE.get_or_init(|| std::env::var("D4R_ZLUDA_IGNORE_DENORMAL").map_or(false, |v| v.trim() == "1"))
|
||||
@@ -1237,7 +1238,6 @@ index e6f22a6..4256ae5 100644
|
||||
+ let mut modes = get_modes_inner(inst);
|
||||
+ if ignore_denormal_modes() {
|
||||
+ modes.denormal_f32 = None;
|
||||
+ modes.denormal_f16f64 = None;
|
||||
+ }
|
||||
+ // d4r: D4R_ZLUDA_DEBUG_MODES=1 prints instructions that need a non-default rounding mode
|
||||
+ if std::env::var("D4R_ZLUDA_DEBUG_MODES").map_or(false, |v| v == "1") {
|
||||
|
||||
Executable
+32
@@ -0,0 +1,32 @@
|
||||
#!/usr/bin/env bash
|
||||
# Reject Linux release libraries that need a newer GLIBC than the target runtime.
|
||||
# Usage: check_glibc_compat.sh MAX_GLIBC LIBRARY [LIBRARY ...]
|
||||
set -euo pipefail
|
||||
|
||||
if [[ $# -lt 2 || ! "$1" =~ ^[0-9]+\.[0-9]+$ ]]; then
|
||||
printf 'usage: %s MAX_GLIBC LIBRARY [LIBRARY ...]\n' "$0" >&2
|
||||
exit 2
|
||||
fi
|
||||
max="GLIBC_$1"
|
||||
shift
|
||||
command -v readelf >/dev/null || { echo 'readelf is required to check GLIBC compatibility' >&2; exit 2; }
|
||||
|
||||
failed=0
|
||||
for library in "$@"; do
|
||||
if [[ ! -f "$library" ]]; then
|
||||
printf 'missing library: %s\n' "$library" >&2
|
||||
failed=1
|
||||
continue
|
||||
fi
|
||||
if ! versions="$(readelf -W --version-info "$library" 2>&1)"; then
|
||||
printf 'cannot inspect %s: %s\n' "$library" "$versions" >&2
|
||||
failed=1
|
||||
continue
|
||||
fi
|
||||
required="$(printf '%s\n' "$versions" | grep -Eo 'GLIBC_[0-9]+\.[0-9]+' | sort -Vu | tail -1 || true)"
|
||||
if [[ -n "$required" && "$(printf '%s\n%s\n' "$max" "$required" | sort -Vu | tail -1)" != "$max" ]]; then
|
||||
printf '%s requires %s (target: at most %s)\n' "$library" "$required" "$max" >&2
|
||||
failed=1
|
||||
fi
|
||||
done
|
||||
exit "$failed"
|
||||
@@ -13,6 +13,7 @@
|
||||
# D4R_ROCM_DIR ROCm with clang, for the kernels default /opt/rocm
|
||||
# D4R_ROCM_RUNTIME ROCm runtime bundled as d4r/rocm (scripts/fetch_rocm_runtime.sh)
|
||||
# default ~/.cache/d4r-rocm-runtime
|
||||
# D4R_MAX_GLIBC highest GLIBC ABI the Linux libraries may require default 2.41
|
||||
# D4R_GPU_ARCHS GPU targets to build kernels for default gfx1100 gfx1101 gfx1102 gfx1103 gfx1200 gfx1201
|
||||
# (RDNA4 targets also get a <target>-fp8 folder: the kernels for d4r.ini NativeFp8 = on)
|
||||
# D4R_OPTISCALER_LICENSE OptiScaler's LICENSE (GPL-3.0) text; default: the system's SPDX copy
|
||||
@@ -101,6 +102,8 @@ cp "$ROOT/build/d4r_nvngx.dll" "$STAGE/d4r/nvngx.dll"
|
||||
cp "$ROOT/build/wine-nvcuda/x86_64-unix/nvcuda.dll.so" "$STAGE/d4r/nvcuda.dll"
|
||||
cp "$ZLUDA/libnvcuda.so" "$STAGE/d4r/zluda/libcuda.so"
|
||||
cp -r "$ROCM_RUNTIME/lib" "$STAGE/d4r/rocm/lib"
|
||||
"$ROOT/scripts/check_glibc_compat.sh" "${D4R_MAX_GLIBC:-2.41}" \
|
||||
"$STAGE/d4r/nvcuda.dll" "$STAGE/d4r/zluda/libcuda.so" "$STAGE/d4r/rocm/lib/"*
|
||||
cp "$ROOT/packaging/d4r.ini" "$STAGE/d4r/d4r.ini"
|
||||
cp "$ROOT/packaging/d4r-check.sh" "$STAGE/d4r/d4r-check.sh"
|
||||
if [[ "$VARIANT" == full ]]; then
|
||||
|
||||
+101
-14
@@ -221,6 +221,7 @@ struct CudaApi
|
||||
int(WINAPI* ctxSynchronize)() = nullptr;
|
||||
int(WINAPI* eventCreate)(CudaEvent*, unsigned int) = nullptr;
|
||||
int(WINAPI* eventRecord)(CudaEvent, void*) = nullptr;
|
||||
int(WINAPI* eventSynchronize)(CudaEvent) = nullptr;
|
||||
int(WINAPI* eventElapsedTime)(float*, CudaEvent, CudaEvent) = nullptr;
|
||||
int(WINAPI* eventDestroy)(CudaEvent) = nullptr;
|
||||
// Optional: overlapped staging (see async_copies()).
|
||||
@@ -656,6 +657,16 @@ static double profile_ms(ProfileClock::time_point start, ProfileClock::time_poin
|
||||
return std::chrono::duration<double, std::milli>(end - start).count();
|
||||
}
|
||||
|
||||
static double profile_thread_cpu_ms()
|
||||
{
|
||||
FILETIME created = {}, exited = {}, kernel = {}, user = {};
|
||||
if (!GetThreadTimes(GetCurrentThread(), &created, &exited, &kernel, &user))
|
||||
return -1.0;
|
||||
const uint64_t kernelTicks = (static_cast<uint64_t>(kernel.dwHighDateTime) << 32) | kernel.dwLowDateTime;
|
||||
const uint64_t userTicks = (static_cast<uint64_t>(user.dwHighDateTime) << 32) | user.dwLowDateTime;
|
||||
return static_cast<double>(kernelTicks + userTicks) / 10000.0;
|
||||
}
|
||||
|
||||
// --- CUDA worker thread --------------------------------------------------------
|
||||
// Every NGX-core and CUDA call runs on this thread so the ZLUDA context that
|
||||
// the nvcuda bridge creates on first use stays current.
|
||||
@@ -1292,14 +1303,18 @@ static bool load_libraries()
|
||||
g.cu.outputKernelNative = nullptr;
|
||||
if (!load_export(g.cuda, "d4rRegisterLinearTexture", g.cu.registerLinearTexture))
|
||||
g.cu.registerLinearTexture = nullptr;
|
||||
if (profile_enabled())
|
||||
if (profile_enabled() || env_uint("D4R_SHIM_BLOCKING_SYNC", 0) != 0)
|
||||
{
|
||||
const bool events = load_export(g.cuda, "cuEventCreate", g.cu.eventCreate) &&
|
||||
load_export(g.cuda, "cuEventRecord", g.cu.eventRecord) &&
|
||||
load_export(g.cuda, "cuEventElapsedTime", g.cu.eventElapsedTime) &&
|
||||
load_export(g.cuda, "cuEventDestroy", g.cu.eventDestroy);
|
||||
if (!events)
|
||||
const bool create = load_export(g.cuda, "cuEventCreate", g.cu.eventCreate);
|
||||
const bool record = load_export(g.cuda, "cuEventRecord", g.cu.eventRecord);
|
||||
const bool wait = env_uint("D4R_SHIM_BLOCKING_SYNC", 0) != 0
|
||||
? load_export(g.cuda, "d4rEventSynchronize", g.cu.eventSynchronize) : true;
|
||||
const bool destroy = load_export(g.cuda, "cuEventDestroy", g.cu.eventDestroy);
|
||||
const bool elapsed = profile_enabled() ? load_export(g.cuda, "cuEventElapsedTime", g.cu.eventElapsedTime) : true;
|
||||
if (profile_enabled() && !(create && record && destroy && elapsed))
|
||||
logf("D4R_PROFILE: CUDA event timing unavailable; CPU stage timings remain enabled");
|
||||
if (env_uint("D4R_SHIM_BLOCKING_SYNC", 0) != 0 && !(create && record && wait && destroy))
|
||||
logf("blocking output wait unavailable; using context sync");
|
||||
}
|
||||
logf("loaded NGX core %ls and nvcuda.dll: %s", corePath, ok ? "all exports present" : "exports missing");
|
||||
return ok;
|
||||
@@ -1484,6 +1499,9 @@ struct FrameTiming
|
||||
double download = 0, outputConvert = 0;
|
||||
double prep = 0, worker = 0, workerWait = 0, finishWait = 0, markerWait = 0;
|
||||
double ngxHost = 0, ctxSync = 0, gpuEval = -1;
|
||||
bool gpuEventsRecorded = false;
|
||||
double outputSyncWall = 0, outputSyncCpu = -1;
|
||||
bool outputSyncBlocking = false;
|
||||
double h2dTotal = 0, d2hIssue = 0, d2hWait = 0;
|
||||
ProfileClock::time_point prepStart, workerQueued, finishQueued;
|
||||
size_t queueDepth = 0;
|
||||
@@ -1536,6 +1554,7 @@ struct Feature
|
||||
int quality = 0, flags = 0;
|
||||
unsigned int preset = 0;
|
||||
CudaEvent profileStart = nullptr, profileEnd = nullptr;
|
||||
CudaEvent outputReadyEvent = nullptr;
|
||||
bool profileEventsReady = false;
|
||||
|
||||
CudaImage color, depth, motion, exposure, output;
|
||||
@@ -1590,6 +1609,7 @@ struct Feature
|
||||
ID3D12Resource* marker = nullptr;
|
||||
volatile uint32_t* markerValue = nullptr;
|
||||
uint32_t frame = 0;
|
||||
uint32_t rejectedFormatCount = 0; // game thread; rate-limits format diagnostics
|
||||
std::atomic<int> latestOutput{-1};
|
||||
std::atomic<uint32_t> completedFrames{0};
|
||||
uint32_t evaluatedFrames = 0; // worker only
|
||||
@@ -3613,7 +3633,40 @@ static void publish_vram(Feature* feature, uint32_t frame, const FrameParams& pa
|
||||
copy.Height = feature->output.height;
|
||||
int result = rowBytes * feature->output.height > buffer.bytes ? -1 : feature->outputRedirected ? 0 : copy_2d(copy);
|
||||
if (result == 0)
|
||||
result = g.cu.ctxSynchronize();
|
||||
{
|
||||
const auto syncStart = timing.enabled ? ProfileClock::now() : ProfileClock::time_point{};
|
||||
const double cpuStart = timing.enabled ? profile_thread_cpu_ms() : -1.0;
|
||||
if (feature->outputReadyEvent != nullptr)
|
||||
{
|
||||
const int recordResult = g.cu.eventRecord(feature->outputReadyEvent, nullptr);
|
||||
const int waitResult = recordResult == 0 ? g.cu.eventSynchronize(feature->outputReadyEvent) : recordResult;
|
||||
if (waitResult == 0)
|
||||
timing.outputSyncBlocking = true;
|
||||
else
|
||||
{
|
||||
logf("frame %u: blocking output wait failed (record %d, wait %d); using context sync", frame,
|
||||
recordResult, waitResult);
|
||||
result = g.cu.ctxSynchronize();
|
||||
g.cu.eventDestroy(feature->outputReadyEvent);
|
||||
feature->outputReadyEvent = nullptr;
|
||||
}
|
||||
}
|
||||
else
|
||||
result = g.cu.ctxSynchronize();
|
||||
if (timing.enabled)
|
||||
{
|
||||
timing.outputSyncWall = profile_ms(syncStart, ProfileClock::now());
|
||||
const double cpuEnd = profile_thread_cpu_ms();
|
||||
if (cpuStart >= 0.0 && cpuEnd >= 0.0)
|
||||
timing.outputSyncCpu = std::max(0.0, cpuEnd - cpuStart);
|
||||
}
|
||||
}
|
||||
if (result == 0 && timing.gpuEventsRecorded)
|
||||
{
|
||||
float gpuEvalMs = -1.0f;
|
||||
if (g.cu.eventElapsedTime(&gpuEvalMs, feature->profileStart, feature->profileEnd) == 0)
|
||||
timing.gpuEval = gpuEvalMs;
|
||||
}
|
||||
if (result != 0)
|
||||
{
|
||||
logf("frame %u: VRAM output copy failed: %d", frame, result);
|
||||
@@ -3802,8 +3855,9 @@ static void run_evaluation(Feature* feature, int slotIndex, uint32_t frame, Fram
|
||||
static const bool evalSync = env_uint("D4R_SHIM_EVAL_SYNC", 1) != 0;
|
||||
const int syncResult = params.vram && !evalSync ? 0 : g.cu.ctxSynchronize();
|
||||
const auto evaluated = ProfileClock::now();
|
||||
const bool gpuEventsRecorded = eventStartResult == 0 && eventEndResult == 0;
|
||||
float gpuEvalMs = -1.0f;
|
||||
if (eventStartResult == 0 && eventEndResult == 0 && syncResult == 0 &&
|
||||
if (gpuEventsRecorded && syncResult == 0 && (!params.vram || evalSync) &&
|
||||
g.cu.eventElapsedTime(&gpuEvalMs, feature->profileStart, feature->profileEnd) != 0)
|
||||
gpuEvalMs = -1.0f;
|
||||
if (params.vram && !gpuWait)
|
||||
@@ -3825,6 +3879,7 @@ static void run_evaluation(Feature* feature, int slotIndex, uint32_t frame, Fram
|
||||
timing.ngxHost = profile_ms(evalStart, evalReturned);
|
||||
timing.ctxSync = profile_ms(syncStart, evaluated);
|
||||
timing.gpuEval = gpuEvalMs;
|
||||
timing.gpuEventsRecorded = gpuEventsRecorded && params.vram && !evalSync;
|
||||
}
|
||||
if (params.vram)
|
||||
{
|
||||
@@ -3988,7 +4043,8 @@ static void finish_publish(Feature* feature, int target, uint32_t frame, const F
|
||||
"d3d_input_record=%.3f d3d_output_record=%.3f game_call=%.3f "
|
||||
"color_convert=%.3f depth_convert=%.3f motion_convert=%.3f exposure_convert=%.3f "
|
||||
"color_h2d=%.3f depth_h2d=%.3f motion_h2d=%.3f exposure_h2d=%.3f "
|
||||
"ngx_host=%.3f ctx_sync=%.3f gpu_eval=%.3f d2h=%.3f output_convert=%.3f "
|
||||
"ngx_host=%.3f ctx_sync=%.3f gpu_eval=%.3f output_sync_wall=%.3f "
|
||||
"output_sync_cpu=%.3f output_sync_blocking=%d d2h=%.3f output_convert=%.3f "
|
||||
"h2d_total=%.3f d2h_issue=%.3f d2h_wait=%.3f "
|
||||
"prep=%.3f worker_wait=%.3f worker=%.3f finish_wait=%.3f finish=%.3f pipeline=%.3f "
|
||||
"throughput_interval=%.3f presented=%u age=%d",
|
||||
@@ -4001,7 +4057,8 @@ static void finish_publish(Feature* feature, int target, uint32_t frame, const F
|
||||
timing.inputRecord, timing.outputRecord, timing.gameCall,
|
||||
timing.convert[0], timing.convert[1], timing.convert[2], timing.convert[3],
|
||||
timing.upload[0], timing.upload[1], timing.upload[2], timing.upload[3],
|
||||
timing.ngxHost, timing.ctxSync, timing.gpuEval, timing.download, timing.outputConvert,
|
||||
timing.ngxHost, timing.ctxSync, timing.gpuEval, timing.outputSyncWall, timing.outputSyncCpu,
|
||||
timing.outputSyncBlocking, timing.download, timing.outputConvert,
|
||||
timing.h2dTotal, timing.d2hIssue, timing.d2hWait,
|
||||
timing.prep, timing.workerWait, timing.worker, timing.finishWait, profile_ms(start, finished),
|
||||
profile_ms(timing.prepStart, finished), interval,
|
||||
@@ -4296,6 +4353,22 @@ D4R_EXPORT NgxResult NVSDK_NGX_D3D12_CreateFeature(ID3D12GraphicsCommandList*, u
|
||||
else
|
||||
feature->scratch = 0;
|
||||
const NgxResult created = g.ngx.createFeature(NGX_FEATURE_SUPER_SAMPLING, p, &feature->cudaHandle);
|
||||
if (created == NGX_SUCCESS && env_uint("D4R_SHIM_BLOCKING_SYNC", 0) != 0 &&
|
||||
g.cu.eventCreate != nullptr && g.cu.eventRecord != nullptr &&
|
||||
g.cu.eventSynchronize != nullptr && g.cu.eventDestroy != nullptr)
|
||||
{
|
||||
// All VRAM-path input waits, NGX kernels and output copies use the null stream.
|
||||
// A blocking event yields the CPU while the GPU finishes that stream.
|
||||
constexpr unsigned int kBlockingSyncNoTiming = 0x1u | 0x2u;
|
||||
const int eventResult = g.cu.eventCreate(&feature->outputReadyEvent, kBlockingSyncNoTiming);
|
||||
if (eventResult != 0)
|
||||
{
|
||||
logf("blocking output wait unavailable (cuEventCreate %d); using context sync", eventResult);
|
||||
feature->outputReadyEvent = nullptr;
|
||||
}
|
||||
else
|
||||
logf("blocking output wait enabled for this feature");
|
||||
}
|
||||
if (created == NGX_SUCCESS && profile_enabled() && g.cu.eventCreate != nullptr &&
|
||||
g.cu.eventRecord != nullptr && g.cu.eventElapsedTime != nullptr && g.cu.eventDestroy != nullptr)
|
||||
{
|
||||
@@ -4396,11 +4469,23 @@ static NgxResult evaluate(ID3D12GraphicsCommandList* list, const NgxHandle* hand
|
||||
colorDesc.Width, colorDesc.Height, colorDesc.Format, depthDesc.Width, depthDesc.Height, depthDesc.Format,
|
||||
motionDesc.Width, motionDesc.Height, motionDesc.Format, outputDesc.Width, outputDesc.Height,
|
||||
outputDesc.Format, exposure);
|
||||
if (!supported_input(Plane::Color, colorDesc.Format) || !supported_input(Plane::Depth, depthDesc.Format) ||
|
||||
!supported_input(Plane::Motion, motionDesc.Format) || !supported_output(outputDesc.Format))
|
||||
const bool colorSupported = supported_input(Plane::Color, colorDesc.Format);
|
||||
const bool depthSupported = supported_input(Plane::Depth, depthDesc.Format);
|
||||
const bool motionSupported = supported_input(Plane::Motion, motionDesc.Format);
|
||||
const bool outputSupported = supported_output(outputDesc.Format);
|
||||
if (!colorSupported || !depthSupported || !motionSupported || !outputSupported)
|
||||
{
|
||||
if (frame <= 3)
|
||||
logf("evaluate frame %u: unsupported format", frame);
|
||||
// Log the first failures even if they occur well after startup, then periodically.
|
||||
const uint32_t rejected = ++feature->rejectedFormatCount;
|
||||
if (rejected <= 3 || rejected % 120 == 0)
|
||||
logf("evaluate feature %u frame %u: unsupported format (rejection %u): "
|
||||
"color %llux%u fmt=%d%s, depth %llux%u fmt=%d%s, "
|
||||
"mv %llux%u fmt=%d%s, output %llux%u fmt=%d%s",
|
||||
feature->handle.Id, frame, rejected,
|
||||
colorDesc.Width, colorDesc.Height, colorDesc.Format, colorSupported ? "" : " (unsupported)",
|
||||
depthDesc.Width, depthDesc.Height, depthDesc.Format, depthSupported ? "" : " (unsupported)",
|
||||
motionDesc.Width, motionDesc.Height, motionDesc.Format, motionSupported ? "" : " (unsupported)",
|
||||
outputDesc.Width, outputDesc.Height, outputDesc.Format, outputSupported ? "" : " (unsupported)");
|
||||
return NGX_FAIL_UNSUPPORTED_FORMAT;
|
||||
}
|
||||
if (exposure != nullptr)
|
||||
@@ -4710,6 +4795,8 @@ static void release_feature(Feature* feature)
|
||||
g.cu.eventDestroy(feature->profileStart);
|
||||
if (feature->profileEnd != nullptr)
|
||||
g.cu.eventDestroy(feature->profileEnd);
|
||||
if (feature->outputReadyEvent != nullptr)
|
||||
g.cu.eventDestroy(feature->outputReadyEvent);
|
||||
if (feature->scratch != 0)
|
||||
g.cu.memFree(feature->scratch);
|
||||
for (CudaDevicePtr buffer : feature->planeLinear)
|
||||
|
||||
@@ -2263,7 +2263,18 @@ CUresult WINAPI cuArrayDestroy(CUarray array)
|
||||
CUARRAYDESTROY_FN function = (CUARRAYDESTROY_FN)find_zluda_symbol("cuArrayDestroy");
|
||||
CUresult result = function != NULL ? function(array) : missing("cuArrayDestroy");
|
||||
if (result == CUDA_SUCCESS)
|
||||
{
|
||||
/* A recycled array handle must not inherit a released feature's output target. */
|
||||
pthread_mutex_lock(&instrumentation_lock);
|
||||
if (redirect_array == array)
|
||||
{
|
||||
redirect_array = NULL;
|
||||
redirect_pointer = 0;
|
||||
redirect_pitch = 0;
|
||||
}
|
||||
pthread_mutex_unlock(&instrumentation_lock);
|
||||
forget_array_descriptor(array);
|
||||
}
|
||||
TRACE_CALL(result, "cuArrayDestroy array=%p result=%d", array, result);
|
||||
return result;
|
||||
}
|
||||
@@ -2537,6 +2548,18 @@ CUresult WINAPI cuEventSynchronize(D4rArg a0)
|
||||
TRACE_CALL(result, "cuEventSynchronize->cuEventSynchronize result=%d", result);
|
||||
return result;
|
||||
}
|
||||
/* The shim's output wait must not inherit D4R_ELIDE_NGX_SYNC: it releases the
|
||||
game's split command list only after this event has actually completed. */
|
||||
CUresult WINAPI d4rEventSynchronize(D4rArg a0)
|
||||
{
|
||||
typedef CUresult(__attribute__((sysv_abi)) * function_type)(D4rArg);
|
||||
function_type function = (function_type)find_zluda_symbol("cuEventSynchronize");
|
||||
CUresult result = function != NULL ? function(a0) : missing("cuEventSynchronize");
|
||||
if (result == CUDA_SUCCESS)
|
||||
flush_kernel_profiles();
|
||||
TRACE_CALL(result, "d4rEventSynchronize result=%d", result);
|
||||
return result;
|
||||
}
|
||||
D4R_FORWARD(cuEventQuery, cuEventQuery, 1, (D4rArg a0), (a0))
|
||||
/* With elided event waits an event may still be pending: report 0 ms instead of CUDA_ERROR_NOT_READY. */
|
||||
CUresult WINAPI cuEventElapsedTime(D4rArg a0, D4rArg a1, D4rArg a2)
|
||||
|
||||
@@ -92,6 +92,7 @@
|
||||
@ stdcall d4rReleaseVulkanMemory(ptr) d4rReleaseVulkanMemory
|
||||
@ stdcall d4rMemcpy2DAsync(ptr ptr) d4rMemcpy2DAsync
|
||||
@ stdcall d4rCtxSynchronize() d4rCtxSynchronize
|
||||
@ stdcall d4rEventSynchronize(ptr) d4rEventSynchronize
|
||||
@ stdcall d4rStreamWaitValue32(int64 long) d4rStreamWaitValue32
|
||||
@ stdcall d4rWriteValue32(int64 long) d4rWriteValue32
|
||||
@ stdcall d4rSetArrayRedirect(ptr int64 long) d4rSetArrayRedirect
|
||||
|
||||
Reference in new issue
Block a user